自作 systemd サービスのログに severity を付与する(bash, python)
画像準備中
概要
自作スクリプト(bash, python)を systemd に登録してサービス化している。
スクリプト内で出力するログに severity を付けるのに苦労したため、まとめた。
条件
- systemd のサービス単位でまとめてログを見たい(
journalctl -u <サービス名>の実行結果に表示されること) - ログを severity 付きで syslog サーバに転送したい
結論
- bash の場合
echo "<SEVERITY_NUMBER>MESSAGE"
- python の場合
print("<SEVERITY_NUMBER>MESSAGE")
環境
概要図
画像準備中
※取り急ぎこんな感じ
 -----------------------------------------------------        -------------------
| bash --> systemd --> journald --> rsyslogd (client) | ---> | rsyslogd (server) |
 -----------------------------------------------------        -------------------
構成
前提
- bash のコードで説明する。
事象とか困っていることとか
step 1
まずは echo するだけの bash スクリプトを作成し、systemd のサービスに登録した。
設定
#!/bin/bash
echo "This is info message."
echo "This is err message."
[Unit]
Description=logging-test

[Service]
Type=simple
ExecStart=bash /tmp/logging-test.bash

[Install]
WantedBy=multi-user.target
実行
[root@server ~]# systemctl start logging-test.service
確認
[root@server ~]# journalctl -u logging-test.service
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 20:56:20 JST. --
 2月 27 20:56:20 server systemd[1]: Started logging-test.
 2月 27 20:56:20 server bash[441780]: This is info message.
 2月 27 20:56:20 server bash[441780]: This is err message.
 2月 27 20:56:20 server systemd[1]: logging-test.service: Succeeded.
※ info 抜粋
[root@server ~]# journalctl -u logging-test.service -p info..info
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 20:56:20 JST. --
 2月 27 20:56:20 server systemd[1]: Started logging-test.
 2月 27 20:56:20 server bash[441780]: This is info message.
 2月 27 20:56:20 server bash[441780]: This is err message.
 2月 27 20:56:20 server systemd[1]: logging-test.service: Succeeded.
※ err 抜粋
[root@server ~]# journalctl -u logging-test.service -p err..err
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 20:56:20 JST. --
-- No entries --
どちらのログも severity は info になっている。
step 2
ここからが本題。This is err message. のログの severity を err にしたい。logger で試してみた。
設定
#!/bin/bash
logger -p info "This is info message."
logger -p err "This is err message."
実行
[root@server ~]# systemctl start logging-test.service
確認
[root@server ~]# journalctl -u logging-test.service
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 20:59:11 JST. --
--- snip ---
 2月 27 20:59:09 server systemd[1]: Started logging-test.
 2月 27 20:59:09 server systemd[1]: logging-test.service: Succeeded.
ログが記録されていない。
systemd のユニット(サービス)のログに記録されるのは、あくまでスクリプト内の標準出力と標準エラー出力のみ。logger は直接 journald (rsyslogd) にログを送っているため、ここには記録されない。
なお、syslog サーバ側では severity 付きでログを受信できている。
調査
systemd のユニット(サービス)としてログを出力しつつ、 severity を指定する方法を探したところ、以下が見つかった。Thank you so much ! 0pointer.de
echo コマンドの頭に severity の識別子を付与するらしい。なんだ、そんな書式聞いたことがない。
echo "<SEVERITY_NUMBER>MESSAGE"
SEVERITY_NUMBER と severity の対応は以下。
| SEVERITY_NUMBER | severity |
|---|---|
| 0 | Emergency |
| 1 | Alert |
| 2 | Critical |
| 3 | Error |
| 4 | Warning |
| 5 | Notice |
| 6 | Informational |
| 7 | Debug |
検証
設定
#!/bin/bash
echo "<6>This is info message."
echo "<3>This is err message."
実行
[root@server ~]# systemctl start logging-test.service
確認
[root@server ~]# journalctl -u logging-test.service
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 21:11:26 JST. --
--- snip ---
 2月 27 21:11:24 server systemd[1]: Started logging-test.
 2月 27 21:11:24 server bash[441844]: This is info message.
 2月 27 21:11:24 server bash[441844]: This is err message.
 2月 27 21:11:24 server systemd[1]: logging-test.service: Succeeded.
※ info 抜粋
[root@server ~]# journalctl -u logging-test.service -p info..info
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 21:11:26 JST. --
--- snip ---
 2月 27 21:11:24 server systemd[1]: Started logging-test.
 2月 27 21:11:24 server bash[441844]: This is info message.
 2月 27 21:11:24 server systemd[1]: logging-test.service: Succeeded.
※ err 抜粋
[root@server ~]# journalctl -u logging-test.service -p err..err
-- Logs begin at Sun 2024-02-25 22:21:52 JST, end at Tue 2024-02-27 21:11:26 JST. --
 2月 27 21:11:24 server bash[441844]: This is err message.
おお、<3>、<6> の文字がログから消えている。面白い。
そして、 severity が付与されている。
syslog サーバ側でも severity 付きで受信できている。
補足
- bash の printf だと以下。
printf "<6>This is info message.\n"
printf "<3>This is err message.\n"
- python だと以下。
print("<6>This is info message.")
print("<3>This is err message.")
- ちなみにログインシェルで実行しても意味はない。
[root@server ~]# echo "<3>This is err message."
<3>This is err message.
- journalctl コマンドに
-o verboseを付けると severity が見える(PRIORITY という項目) 。
[root@server ~]# journalctl -u logging-test.service -o verbose
Tue 2024-02-27 21:57:10.029831 JST [s=e9efc3fea5734e74aa01d2375b257426;i=5b55;b=783be12125304676a886445aea612545;m=27e368ef58;t=6125c90734a>
    SYSLOG_FACILITY=3
    _UID=0
    _GID=0
    _CAP_EFFECTIVE=1ffffffffff
    _BOOT_ID=xxx
    _MACHINE_ID=xxx
    _HOSTNAME=server
    _TRANSPORT=stdout
    PRIORITY=3
    _COMM=bash
    SYSLOG_IDENTIFIER=bash
    _SYSTEMD_UNIT=logging-test.service
    MESSAGE=This is err message.
    _STREAM_ID=xxx
    _PID=442722
    _SYSTEMD_INVOCATION_ID=xxx
あとがき
狐につままれた気分。設定やコーディングで解決するイメージしか持っていなかった。まさか OS の既存の実装に答えがあるとは。。。
参考記事
https://0pointer.de/blog/projects/journal-submit.html
※検索用ワード シビアリティ/セベリティ/プライオリティ/ログレベル
自作キーボード「TBK Mini」を作ってみた

目次
概要
自作キーボードTBK Miniのビルドログ。
経緯
Corne Cherry V3で親指が押しっぱなしになるキーマップを使っていたところ、親指と手首が痛くなった。「親指のポジション」と「手首の角度」を改善するため、3Dケースを使用したキーボードを選択した。
構成
今回作成したキーボードの主要パーツは以下。
- Keyboard: TBK Mini with 30 degrees tents
- Keyswitch: Gateron Caps V2 Switches 3 Pins Milkey Brown
- Keycap: KBDfans NP PBT ブランク キーキャップセット(124キー/ブラック)
準備
以下の工具一式を揃えた。 none06.hatenadiary.org
部材購入
| 部材 | 製品名 | 価格 | 入力先 | 備考 |
|---|---|---|---|---|
| キット | TBK Mini – DIY Kit with case and electronics × 1 uni_cpo_optminikit: Tents (30 degrees) | 28,991(€198.55*1) | https://bastardkb.com/product/tbk-mini-diy-kit-with-case-and-electronics/ | - |
| キースイッチ(MX互換) | Gateron Caps V2 Switches 3 Pins(10個) Milkey Brown | 2,475(495*5) | https://shop.yushakobo.jp/products/2808?variant=40821007286433 | - |
| キーキャップ(MX互換) | KBDfans NP PBT ブランク キーキャップセット(124キー/ブラック) 残り2点 | 3,500(3,500*1) | https://talpkeyboard.net/items/60f7ac3d7291346ddba3f390 | - |
| TRRSケーブル | TRRSケーブル 50cm | 600(600*1) | https://shop.dailycraft.jp/products/trrs_cable_50 | - |
| USBケーブル(TypeA凸-TypeC凸) | - | - | 家に転がっていたもの | - |
| 合計 | - | 35,566 | - | - |
手順書(ビルドガイド)
製作者であるBastard Keyboardsさんのビルドガイドを参照。 docs.bastardkb.com
作業ログ(ビルドログ)
キットと工具の確認
参照:Kit contents and required tools – Bastard Keyboards
テントはオプション。

ケースの準備
参照:Prepare the case – Bastard Keyboards
ネジ穴をケースに取り付ける。
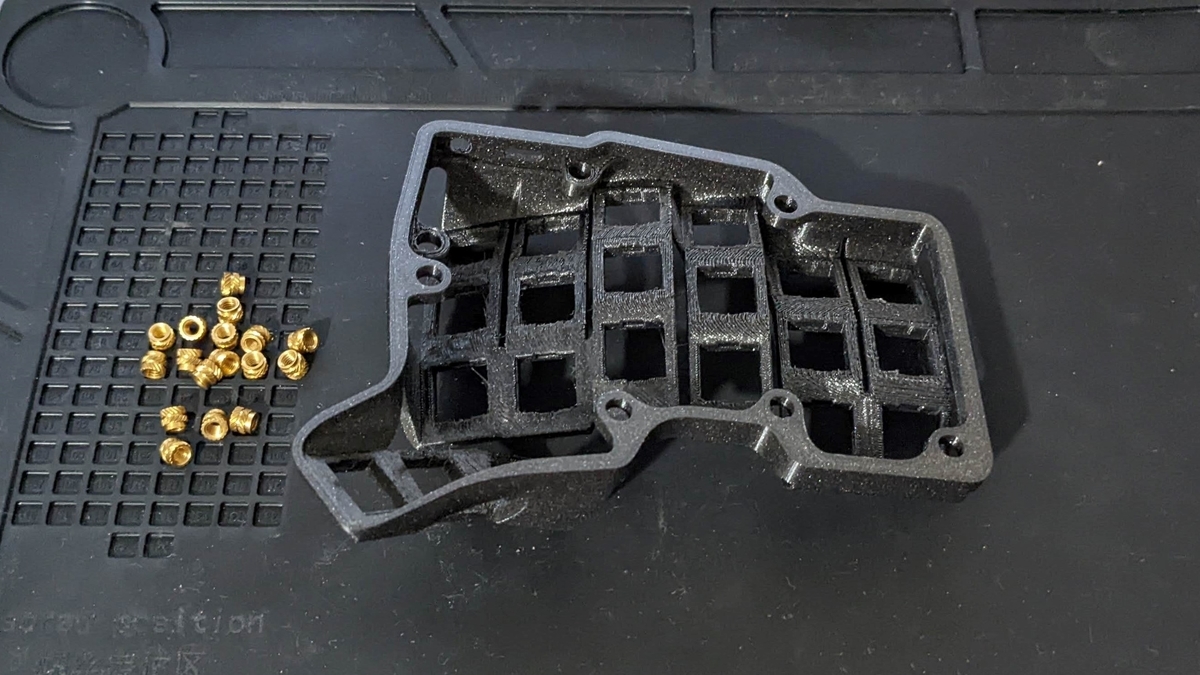
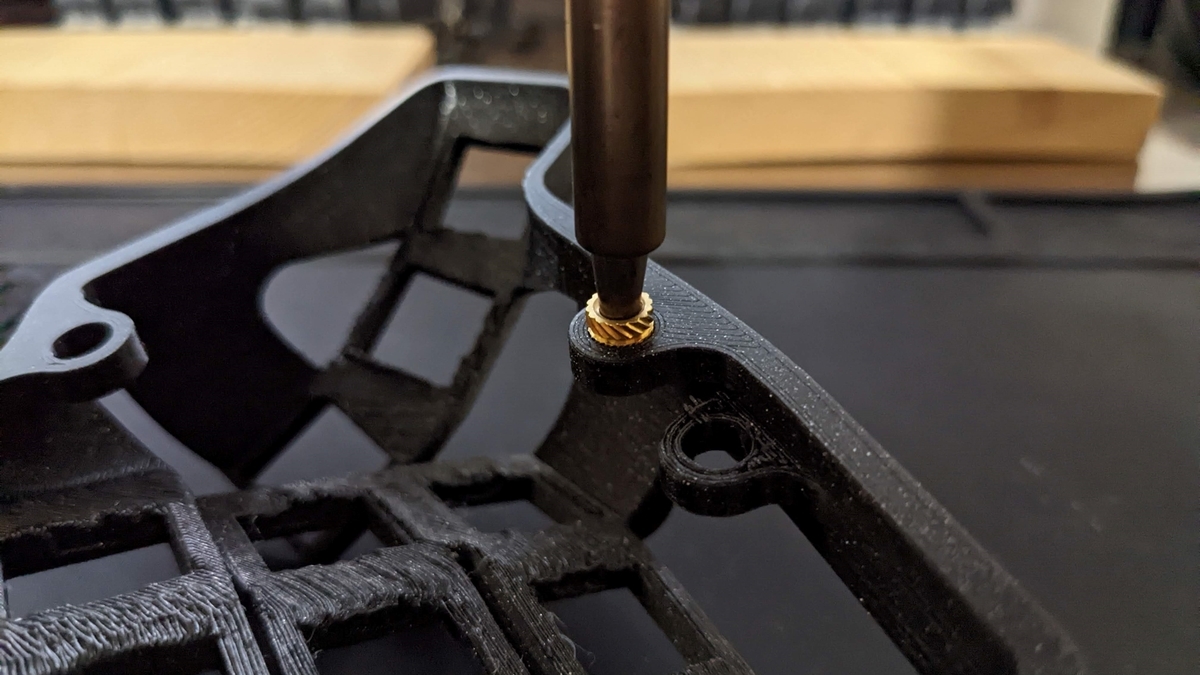
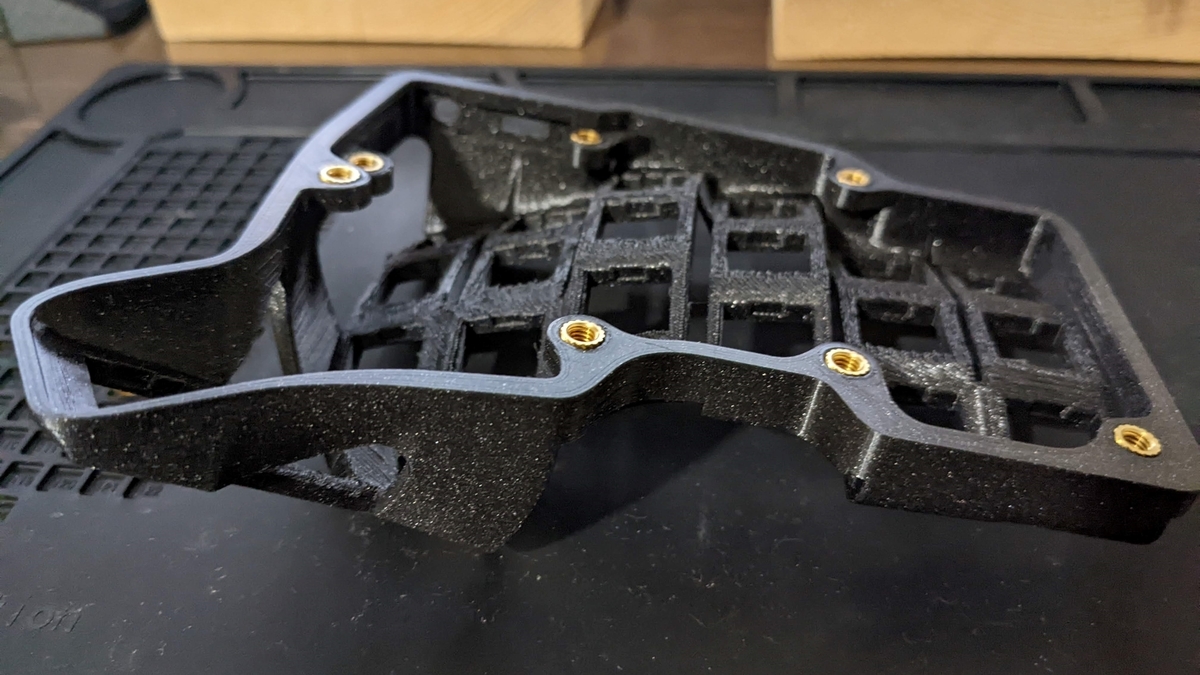
PCBの準備
参照:Prepare the plate and thumb cluster PCBs – Bastard Keyboards
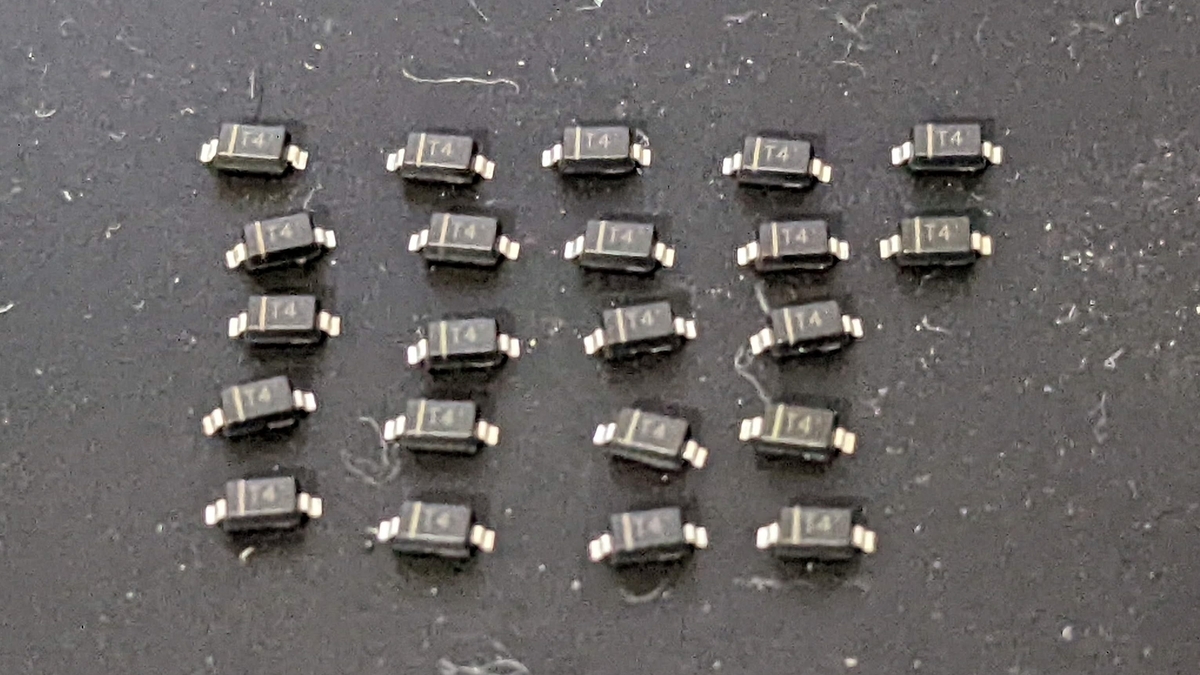
ダイオードをメインPCBとサムクラスターPCBにはんだ付けする。

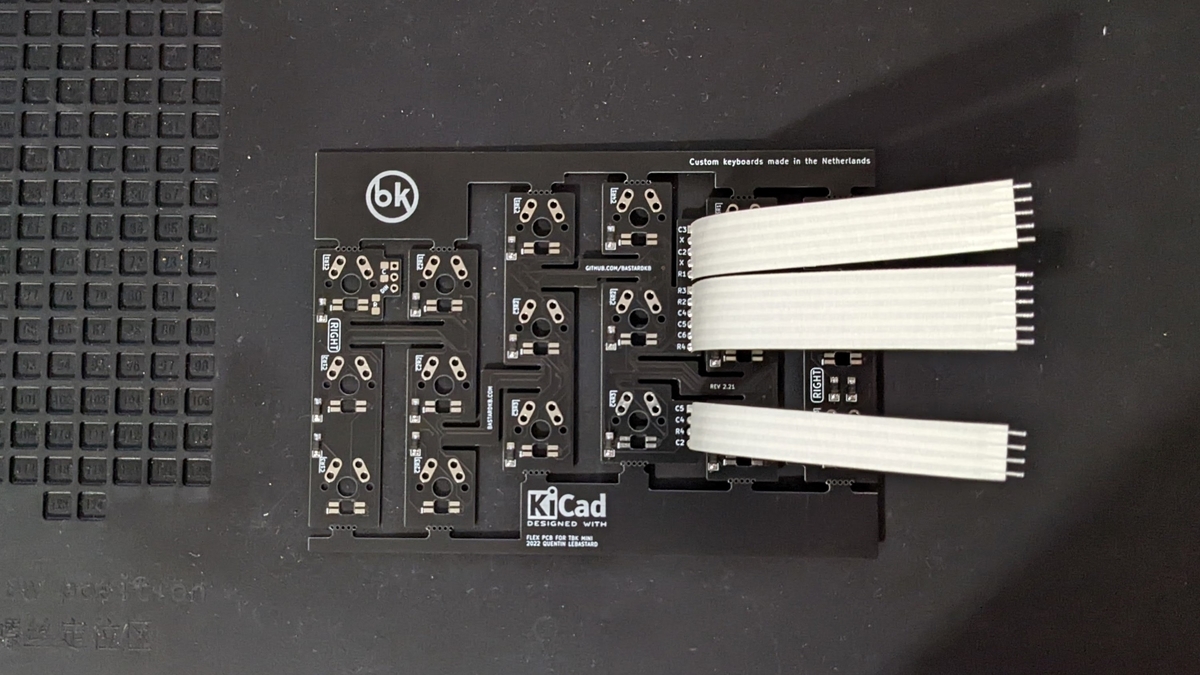
リボンケーブルのはんだ付け
参照:Install the ribbon cables – Bastard Keyboards
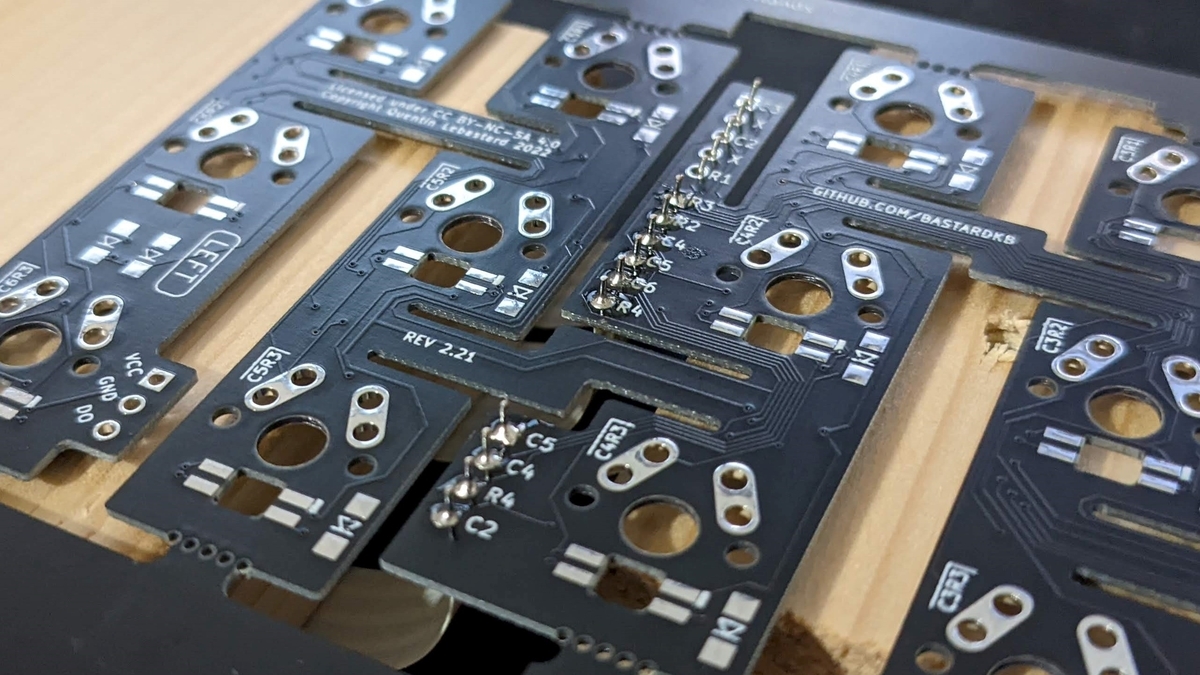
リボンケーブルをはんだ付けする。
Elite-Cの準備
参照:Prepare the Elite-C – Bastard Keyboards
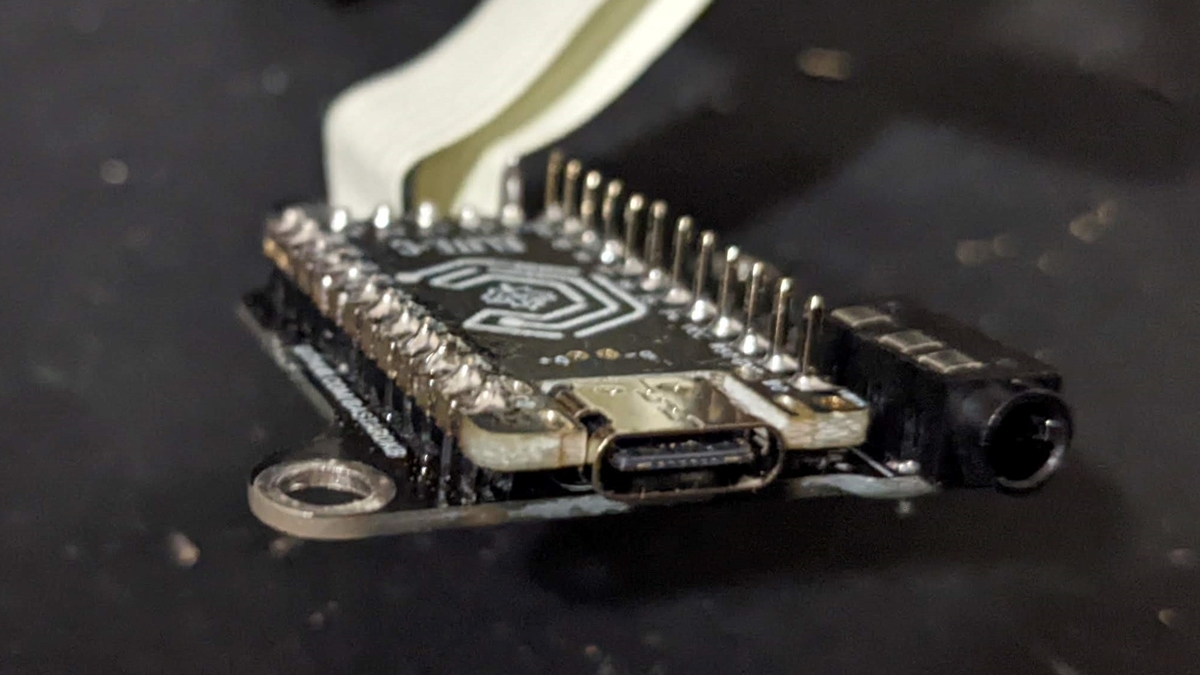
Elite-C
Elite-CをMCU取り付け用PCBにはんだ付けする。
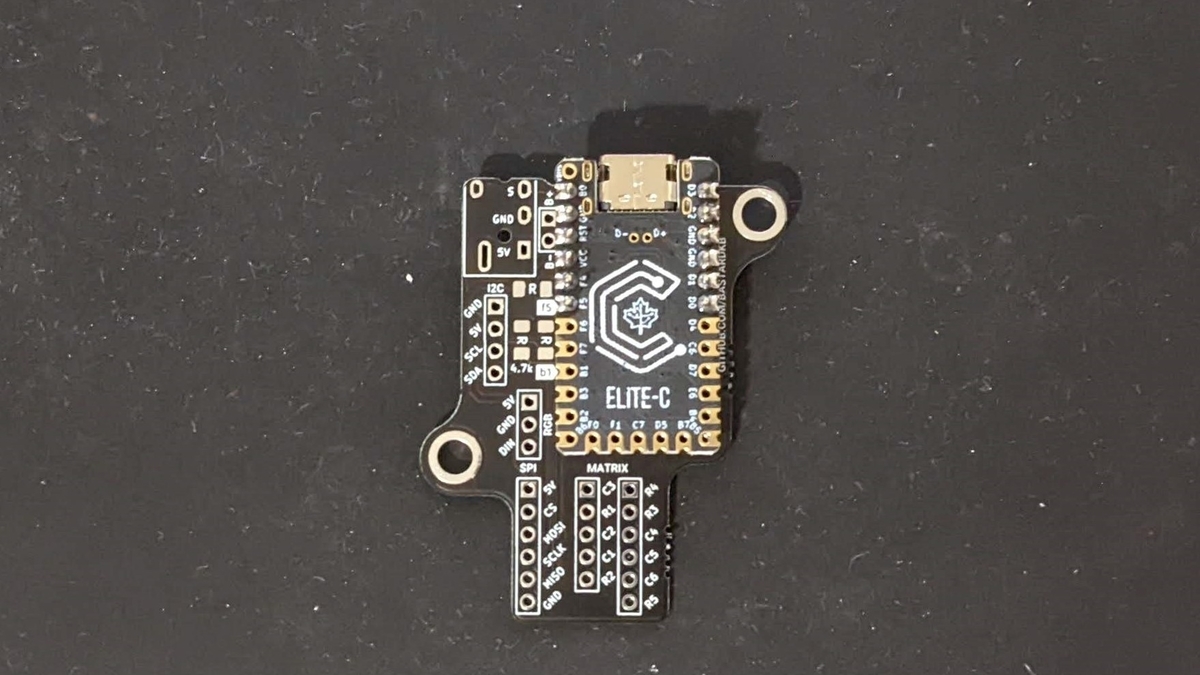
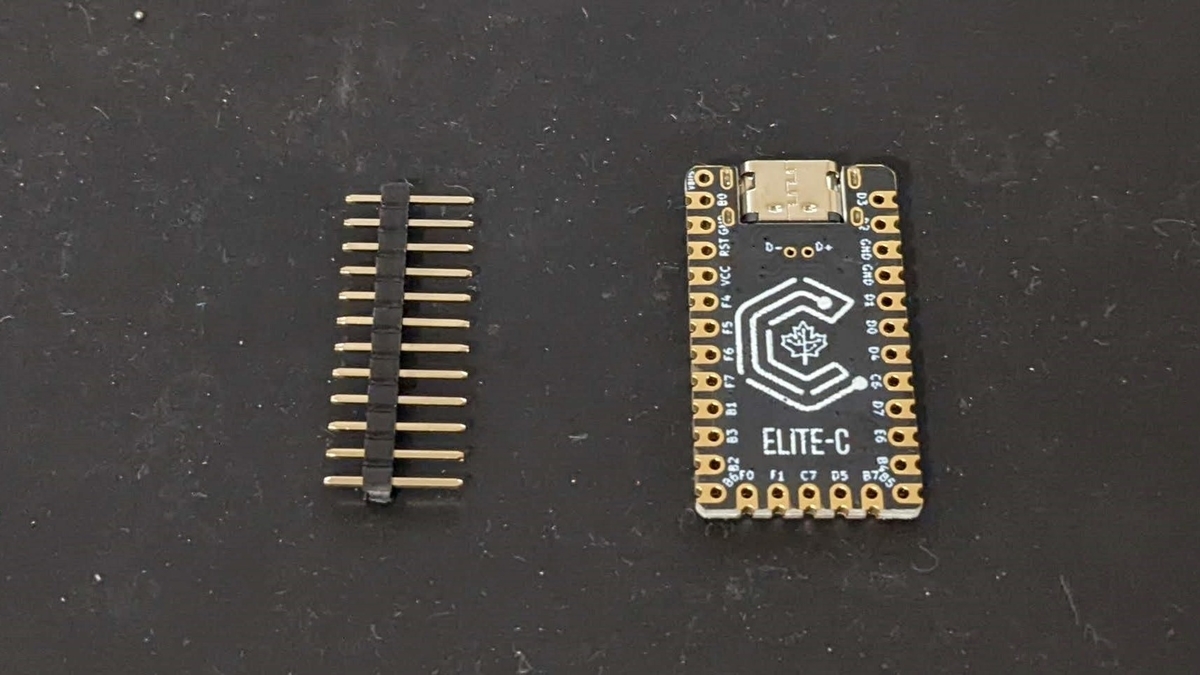 ビルドガイドを読み間違えてElite-C(v1)の手順ではんだ付けしてしまったた。Elite-C(v2)の手順はこちらを参照。
v1では12ピン×1本のピンヘッダを6ピン×2本に折ってはんだ付けする。(写真は誤りなので注意)
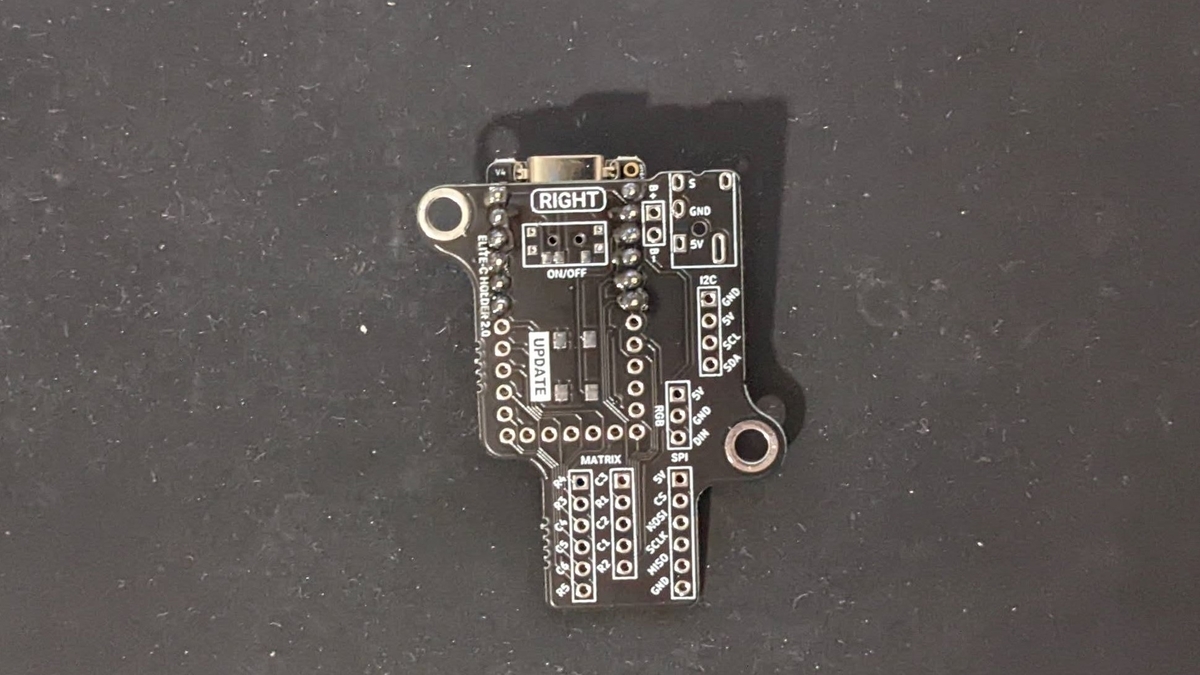 v2では12ピン×2本と5ピン×1本のピンヘッダをはんだ付けする。
なお、ケースに収納する際の干渉を軽減させるため、一部のピンヘッダを短くカットしている(全部短くしても良かったかもしれない)。
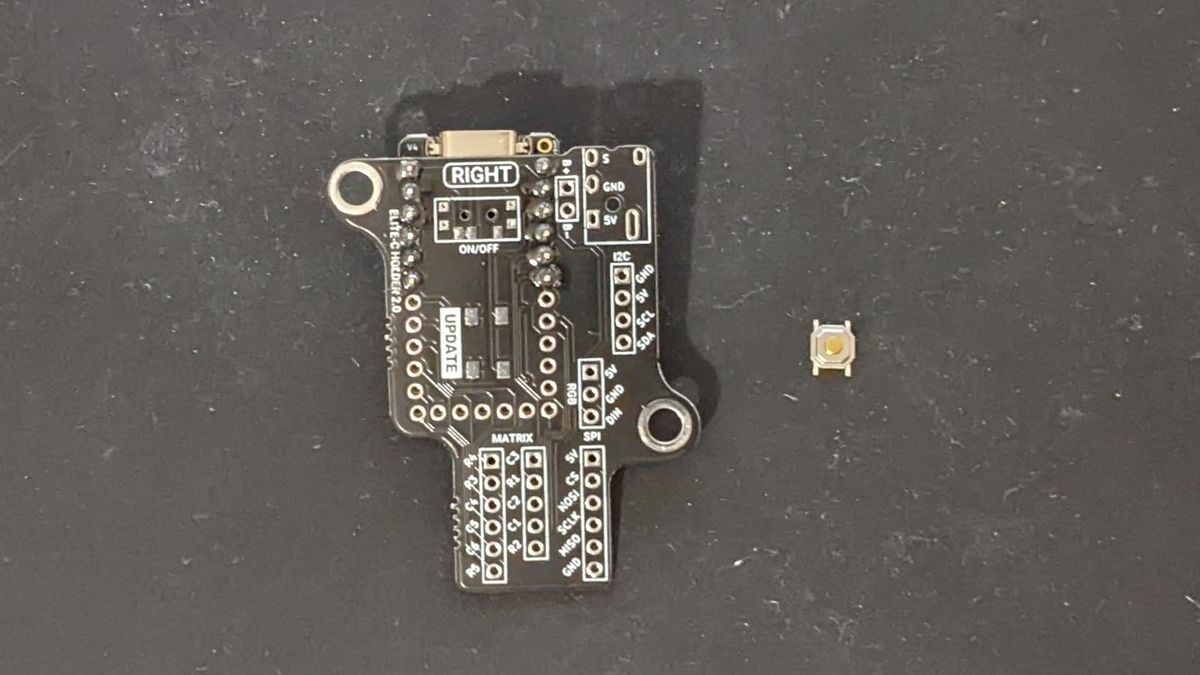
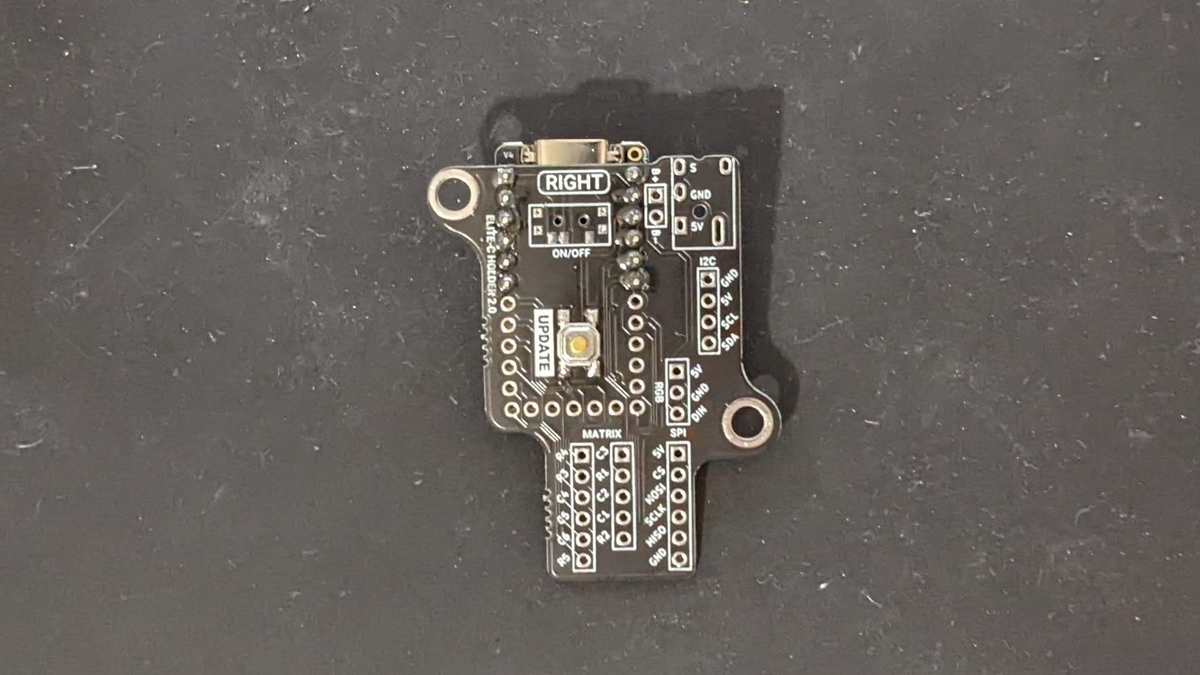
リセットボタン
リセットボタンをMCU取り付け用PCBにはんだ付けする。
オーディオジャック
オーディオジャックをMCU取り付け用PCBにはんだ付けする。

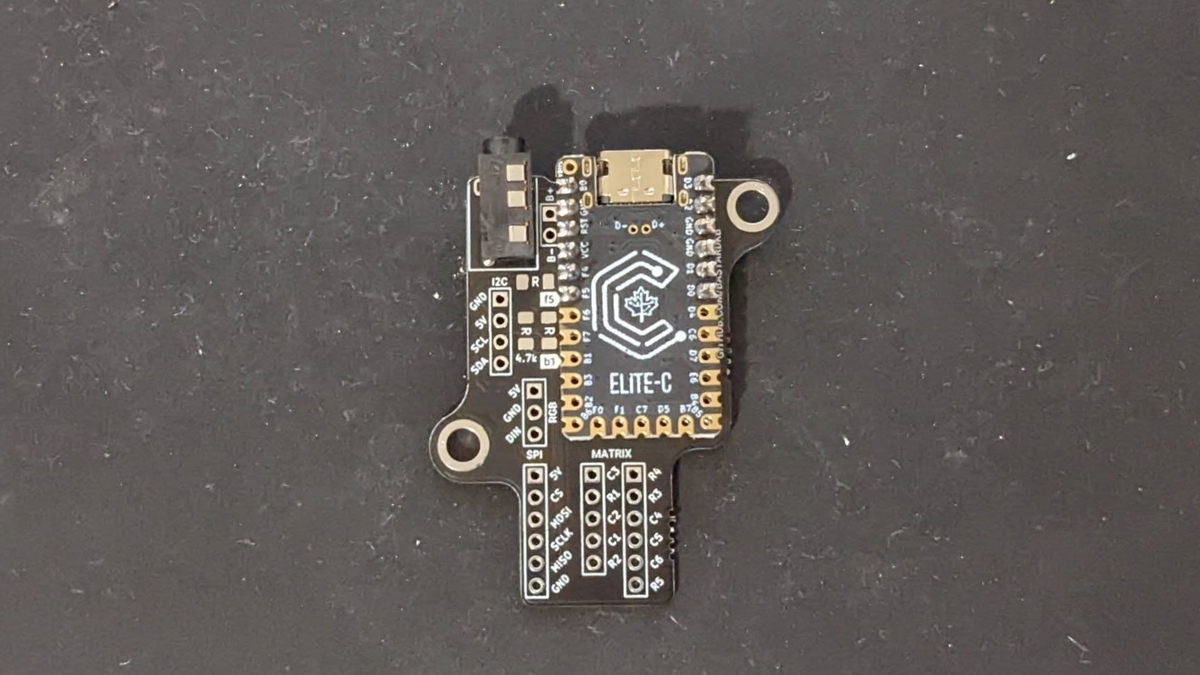
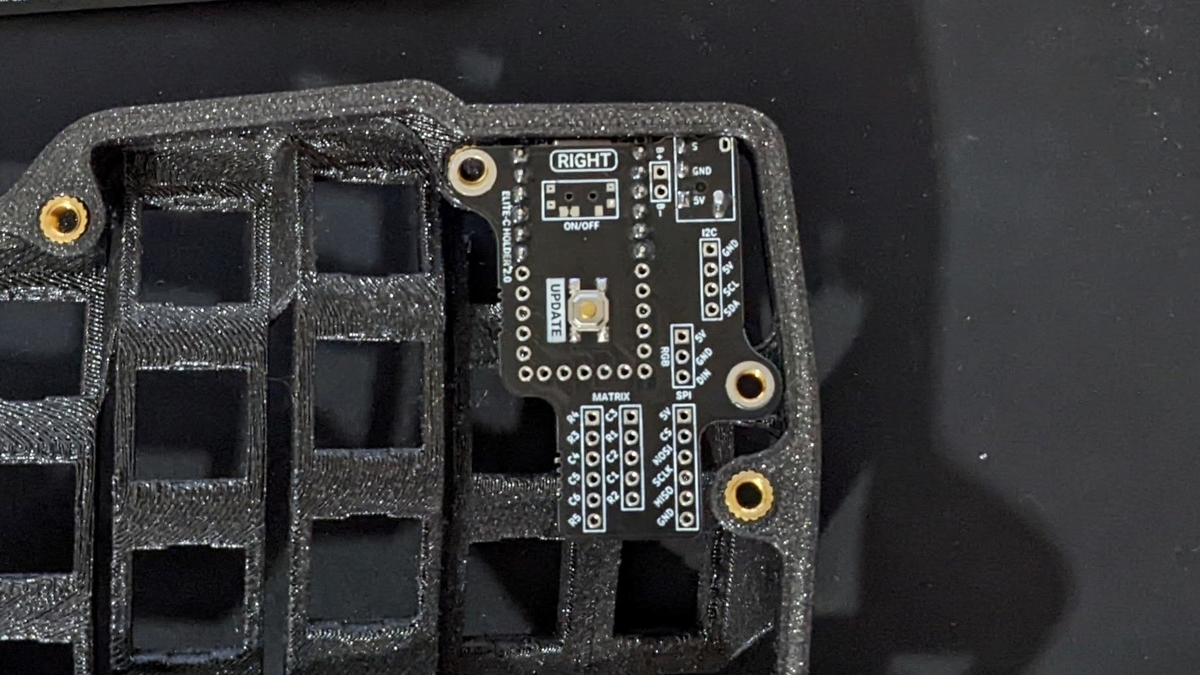
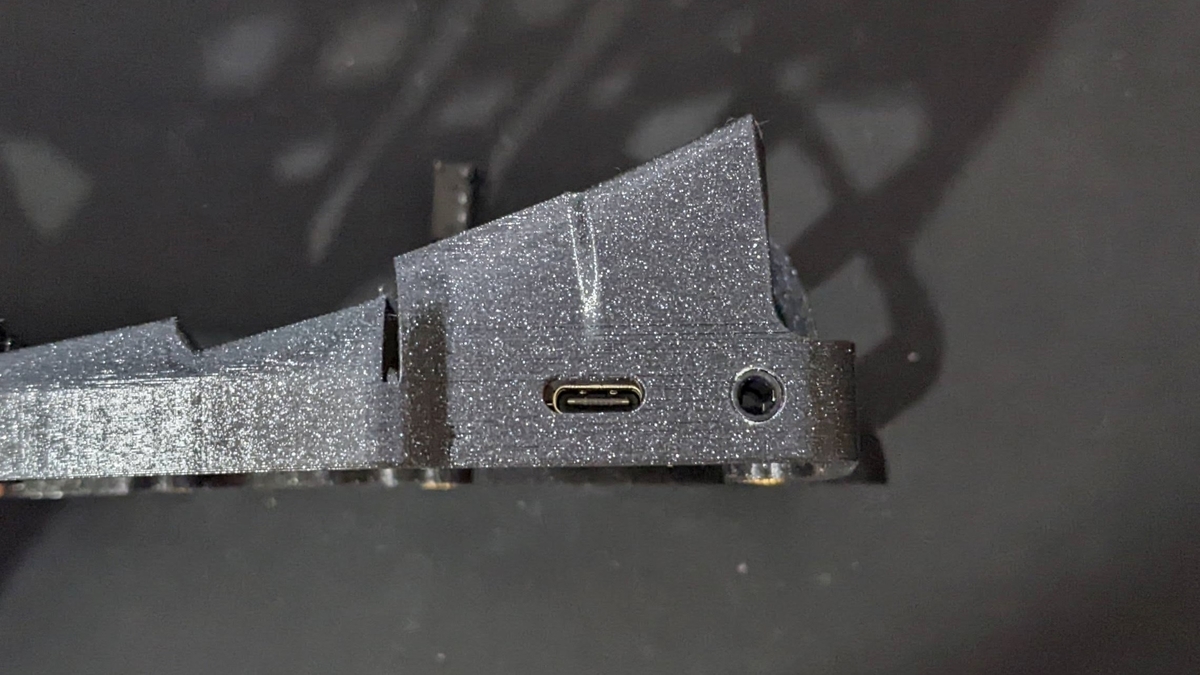
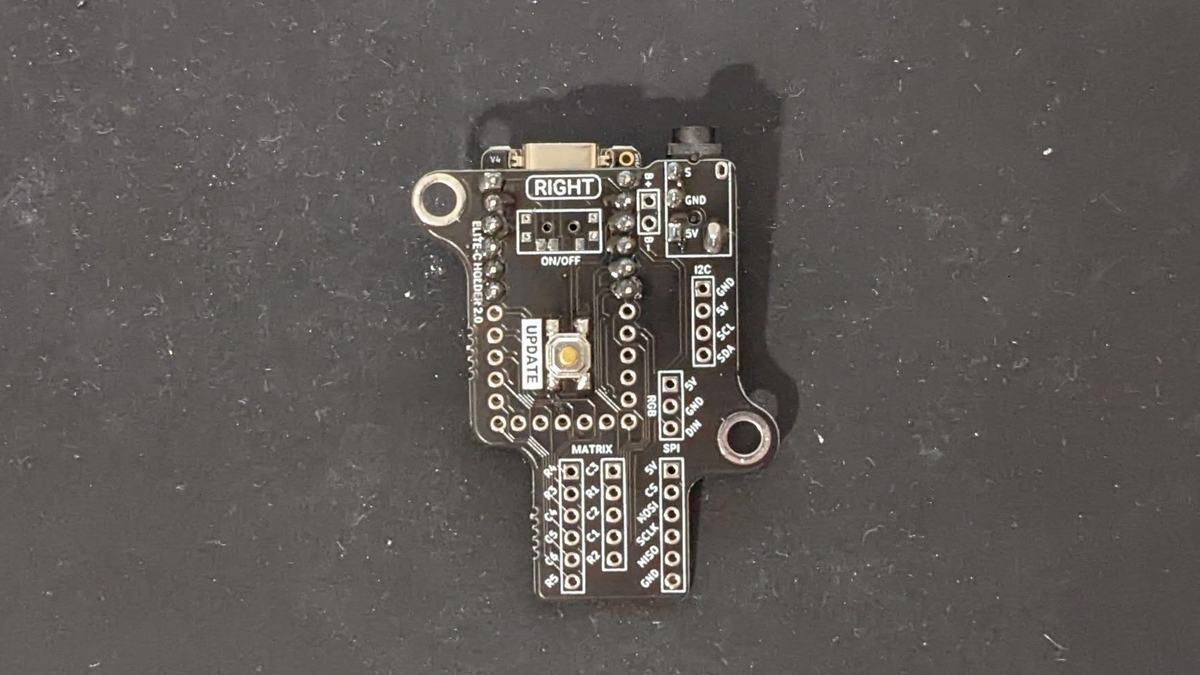 オーディオジャックの穴とUSB端子の穴の位置がシビアなので、一度ケースに取り付けた状態ではんだ付けを微調整すると良い。
リボンケーブルの接続
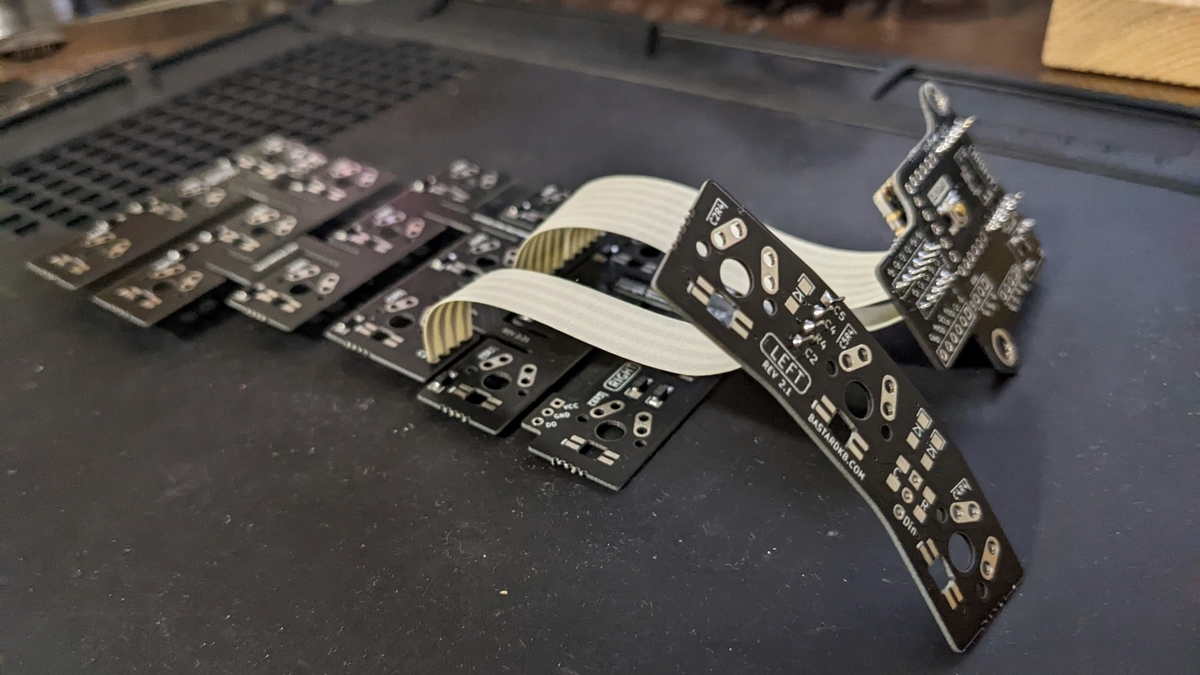
参照:Connect the cables to the Elite-C – Bastard Keyboards
メインPCBから伸びるリボンケーブルをMCU取り付け用PCBとサムクラスターPCBにはんだ付けする。
キースイッチの取り付け
参照:Install the switches – Bastard Keyboards
ケースにキースイッチを取り付ける。


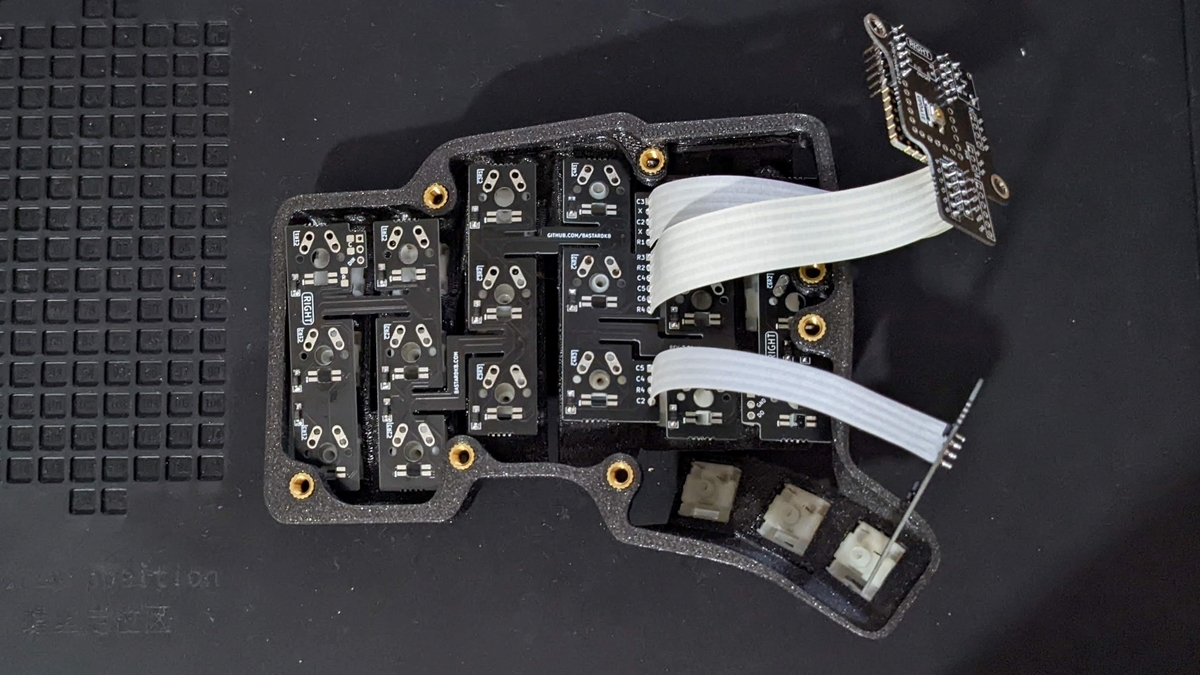
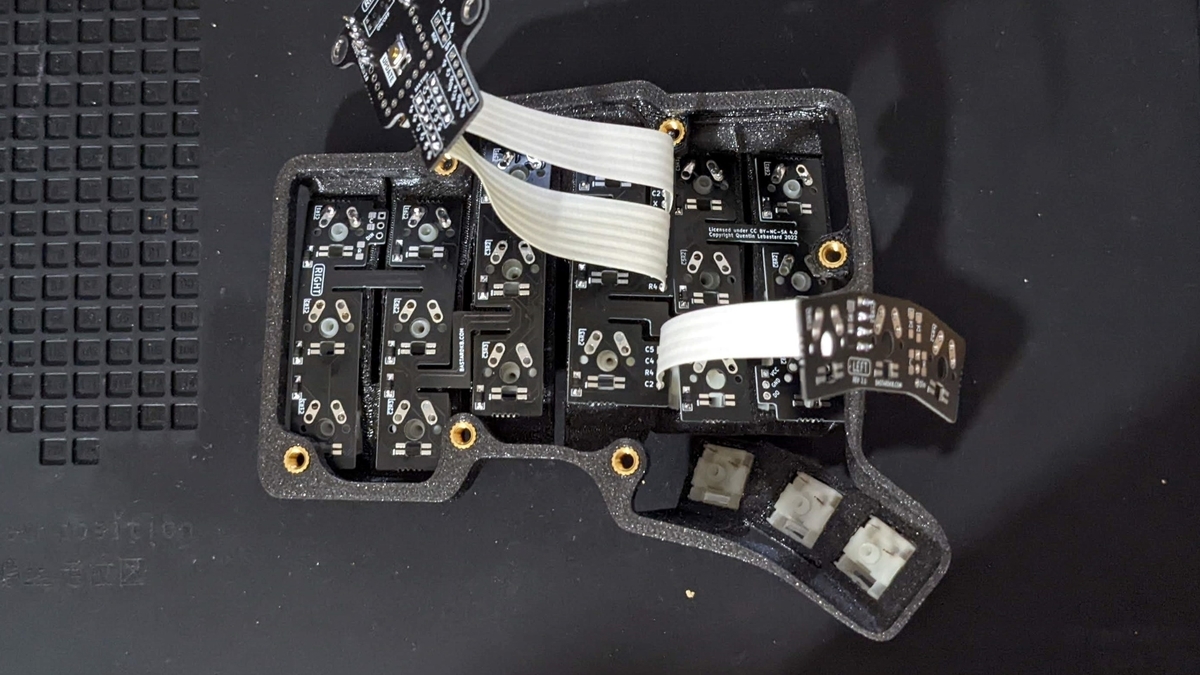
 PCBにキースイッチをはんだ付けする。スイッチソケットを使わず直接はんだ付けする方式。PCBを曲げながらはんだ付けするのはなかなか大変だった。

仕上げ
参照:Install the keyboard – Bastard Keyboards
キーの認識テスト
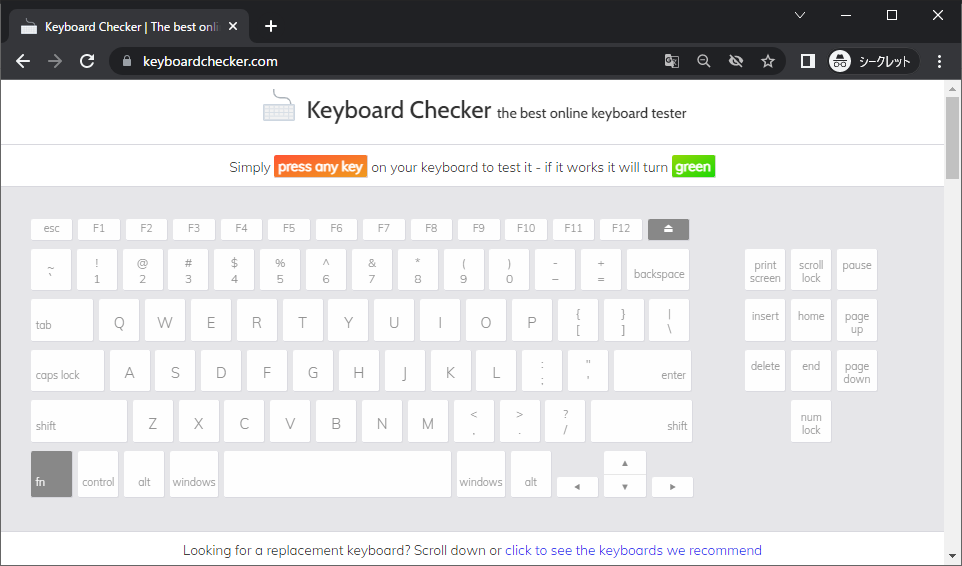
キーの認識テストをする。
https://keyboardchecker.com/
ボトムプレートまたはテントの取り付け
オプションで購入したテントを取り付ける。標準のボトムプレートについては後述。

キーキャップの取り付け
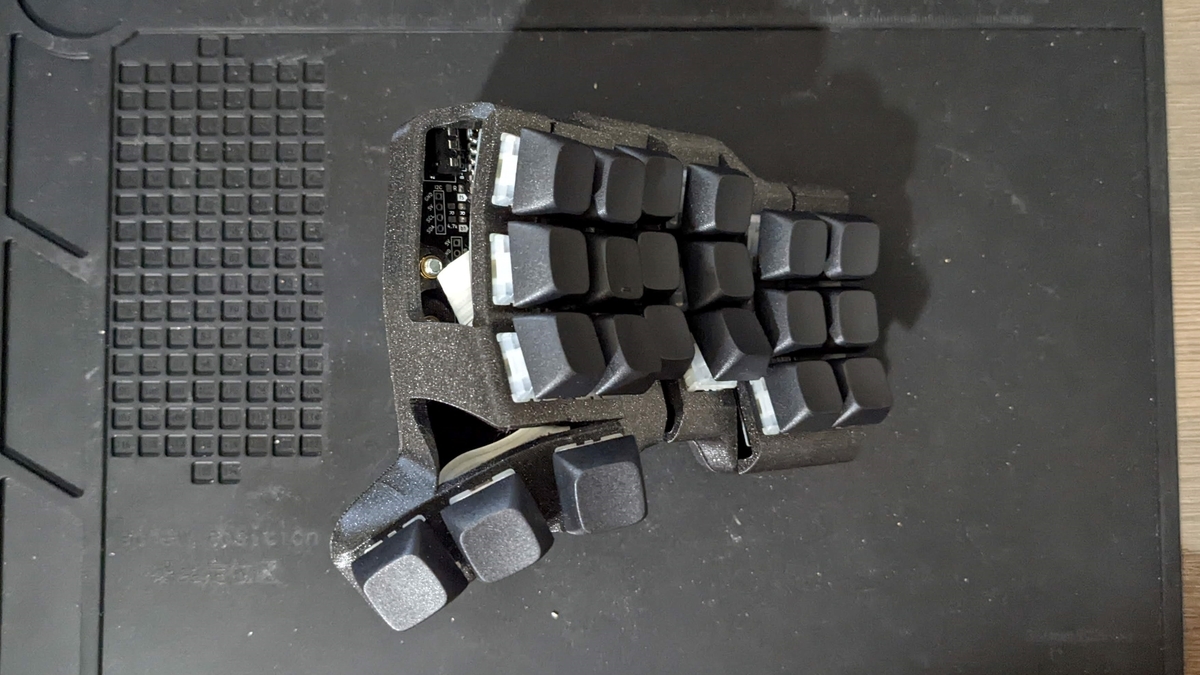
キーキャップを取り付ける。
キーマップのカスタマイズ(オプション)
Vialをインストールし、キーマップをカスタマイズする。
https://get.vial.today/

完成!

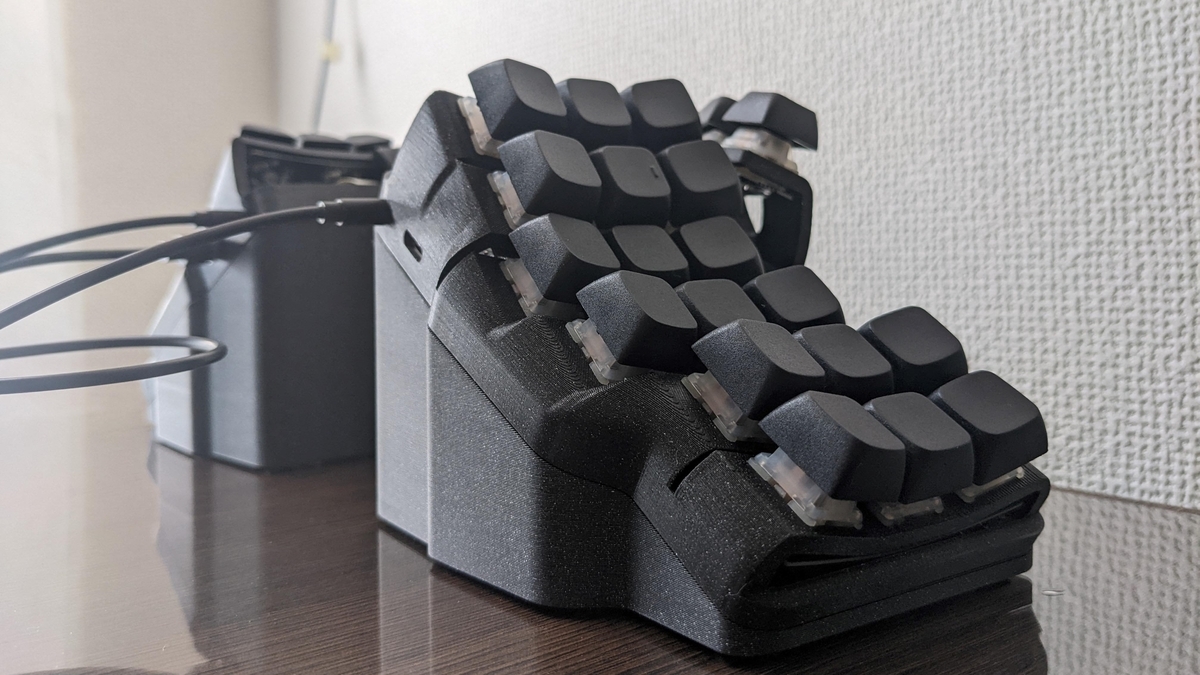
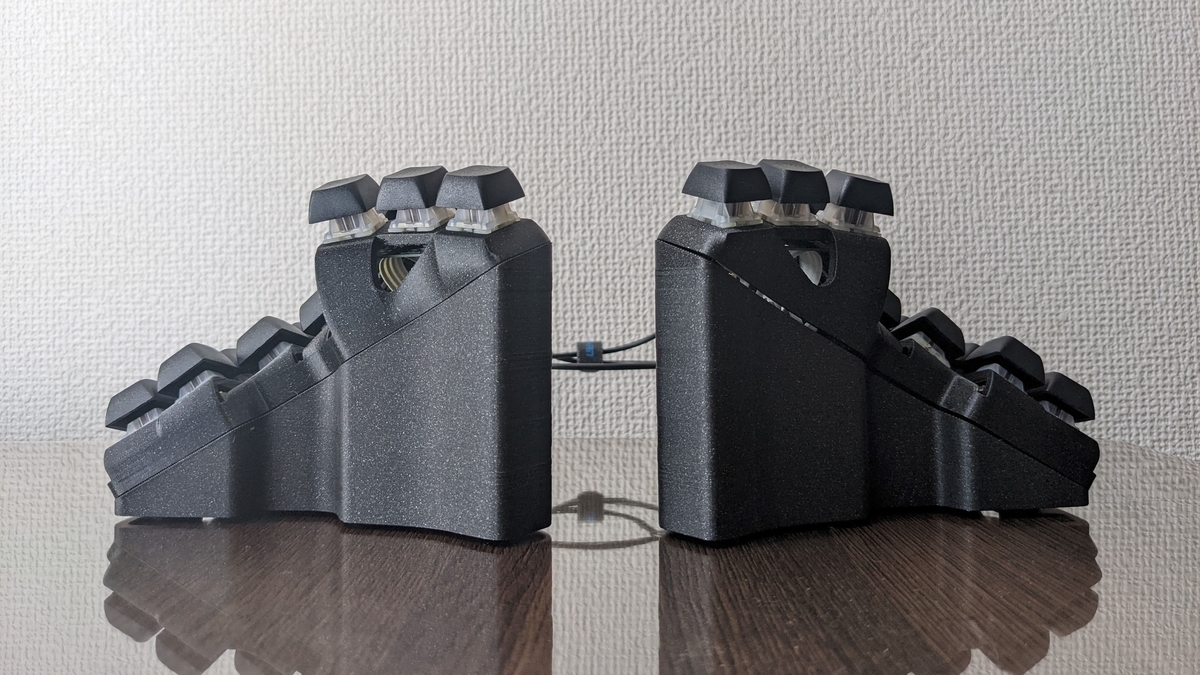
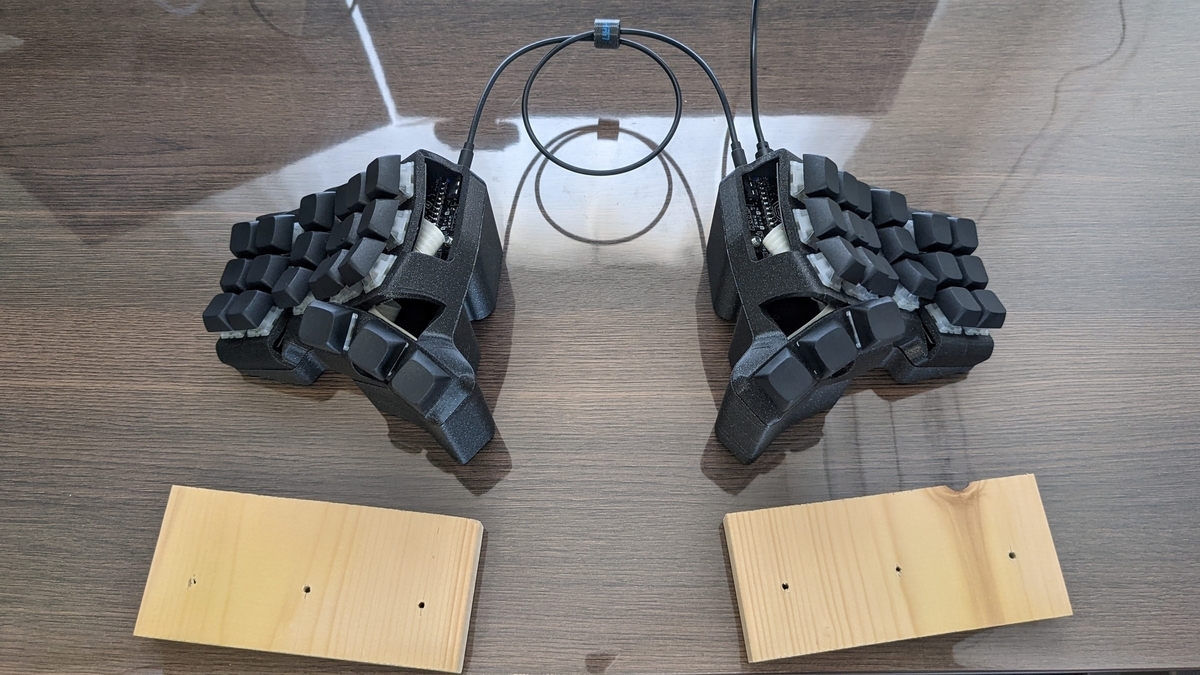 ※リストレスト探し中。当面はそのへんに転がっていた木材の切れ端でしのぐ。
おまけ
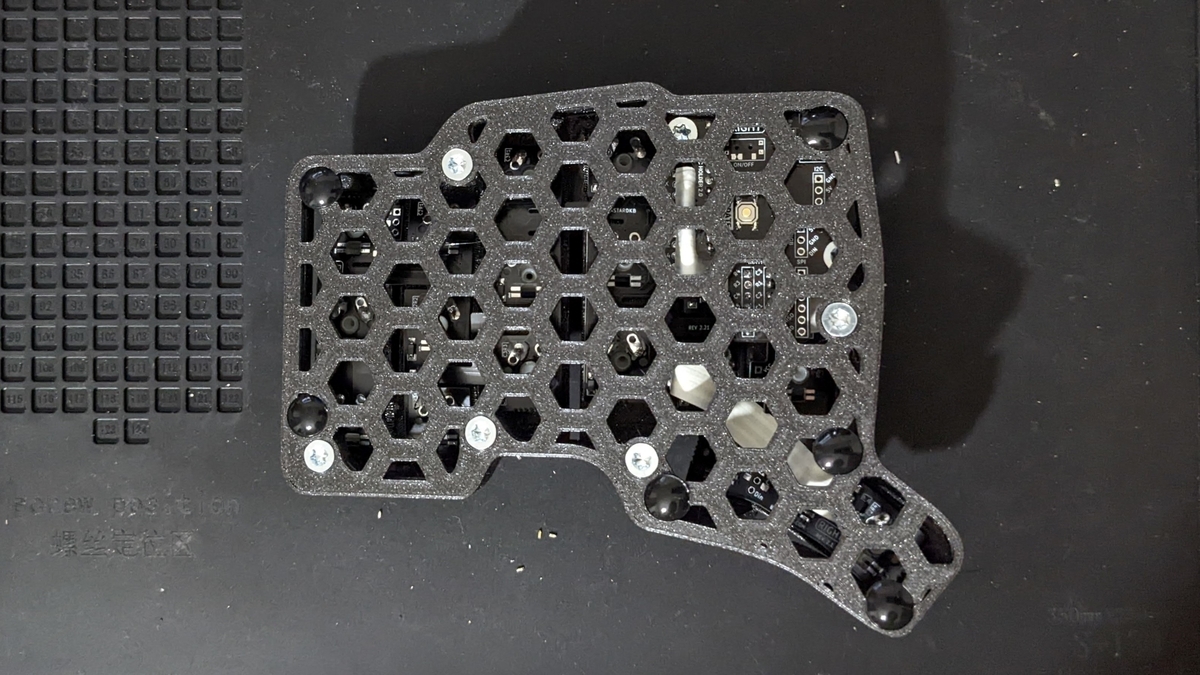
オプションのテントではなく標準のボトムプレートを取り付けるとこんな感じ。リボンケーブルを収納しないといけないが、ピンヘッダがリボンケーブルに干渉するので工夫が必要。
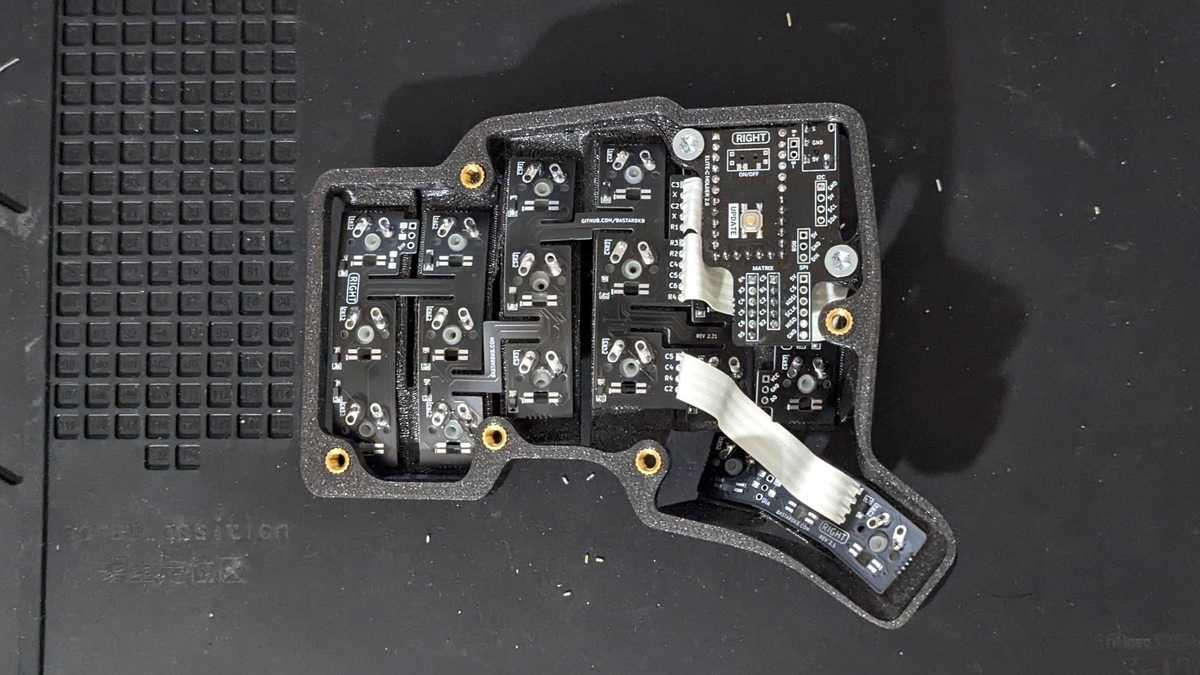
あとがき
親指と手首がとても楽になった。
課題として、テントが思ったより高いため、リストレストを高くしないと指が届きにくいキーがある。
参考記事
Kubernetes環境でDNSサービスを構築してみた
NFSサーバ上に、CoreDNS起動時に読み込ませる設定ファイルを作成する。 NFSサーバ上に、CoreDNSで名前解決に使用するファイルを作成する。 Podにマウントする永続ボリューム(PV、PVC)を作成する。 マニフェストを適用する。 PV、PVCが作成されていることを確認する。 CoreDNSのPodをデプロイするDeploymentを作成する。 マニフェストを適用する。 Podが作成されていることを確認する。 PodのログからCoreDNSが起動していることを確認できる。 補足だが、Podを作成したタイミングでワーカノード上にPVがNFSマウントされていることを確認できる。 CoreDNSのPodをKubernetesクラスタ外部に公開するためのServiceを作成する。当環境ではServiceの マニフェストを適用する。 サービスが作成されていることを確認する。 任意のマシンから名前解決できることを確認する。 CoreDNSのログにリクエストが記録されていることが確認できる。 あれ、53/TCPって必要なんだっけ・・・?
全編目次
概要
環境
概要図
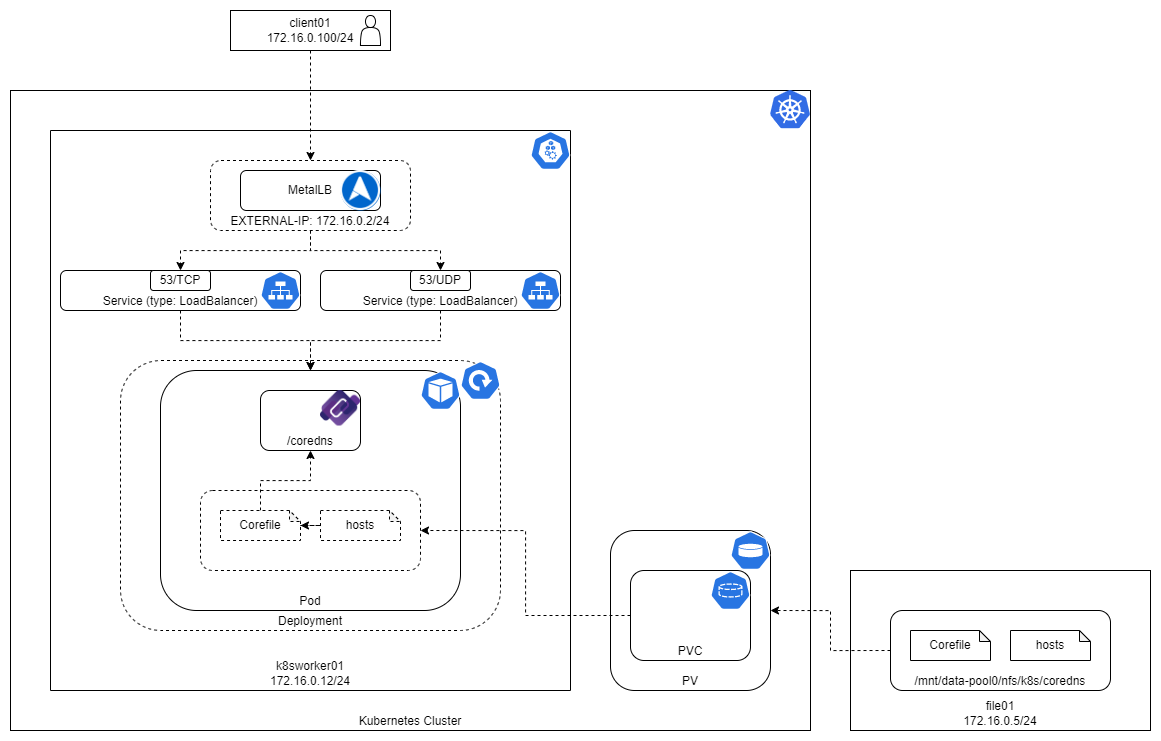
構成
ホスト名
IPアドレス
OS
用途
備考
k8sctrpln01
172.16.0.11/24
CentOS 7.9.2009
コントロールプレーンノード
QEMU+KVM仮想ゲスト
k8sworker01
172.16.0.12/24
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
k8sworker02
172.16.0.13/24
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
dns02
172.16.0.2/24
CoreDNS-1.9.3
DNSサービス
MetalLB 仮想IP
file01
172.16.0.5/24
TrueNAS-12.0-U6
NFSサーバ
-
前提
kubectlコマンドの実行は、クライアントマシン(Windows 10)上で行う。Windowsへのkubectlコマンドのインストールは以下を参照。
kubernetes.io構築
Corefileの作成
. {
    whoami
    errors
    log . "{remote} is Request: {name} {type} {>id}"
    hosts /etc/coredns/hosts {
      fallthlough
    }
    reload
}
hostsファイルの作成
172.16.0.11     k8sctlpln011.tmpdomain.local    k8sctlpln01.tmpdomain.local     k8sctlpln011     k8sctlpln01
172.16.0.12     k8sworker011.tmpdomain.local    k8sworker01.tmpdomain.local     k8sworker011     k8sworker01
172.16.0.13     k8sworker021.tmpdomain.local    k8sworker02.tmpdomain.local     k8sworker021     k8sworker02
PV、PVCの作成
apiVersion: v1
kind: PersistentVolume
metadata:
  name: pv-nfs-coredns
  labels:
    volume: volume-nfs-coredns
spec:
  capacity:
    storage: 10Gi
  volumeMode: Filesystem
  accessModes:
  - ReadWriteOnce
  persistentVolumeReclaimPolicy: Retain
  storageClassName: slow
  mountOptions:
  - hard
  - nfsvers=3
  nfs:
    path: "/mnt/data-pool0/nfs/k8s/coredns"
    server: file01
---
apiVersion: v1
kind: PersistentVolumeClaim
metadata:
  name: pvc-nfs-coredns
spec:
  accessModes:
  - ReadWriteOnce
  volumeMode: Filesystem
  resources:
    requests:
      storage: 2Gi
  storageClassName: slow
  selector:
    matchLabels:
      volume: volume-nfs-coredns
$ kubectl apply -f pv-nfs-coredns.yaml
persistentvolume/pv-nfs-coredns created
persistentvolumeclaim/pvc-nfs-coredns created
$ kubectl get pv pv-nfs-coredns
NAME             CAPACITY   ACCESS MODES   RECLAIM POLICY   STATUS   CLAIM                     STORAGECLASS   REASON   AGE
pv-nfs-coredns   10Gi       RWO            Retain           Bound    default/pvc-nfs-coredns   slow                    67s
$ kubectl get pvc pvc-nfs-coredns
NAME              STATUS   VOLUME           CAPACITY   ACCESS MODES   STORAGECLASS   AGE
pvc-nfs-coredns   Bound    pv-nfs-coredns   10Gi       RWO            slow           72s
Deploymentの作成
apiVersion: apps/v1
kind: Deployment
metadata:
  name: coredns-deployment
spec:
  selector:
    matchLabels:
      app: coredns
  replicas: 2
  template:
    metadata:
      labels:
        app: coredns
    spec:
      containers:
      - name: coredns
        image: coredns/coredns
        ports:
        - name: tcp
          containerPort: 53
          protocol: TCP
        - name: udp
          containerPort: 53
          protocol: UDP
        volumeMounts:
        - name: volume-nfs-coredns
          mountPath: /etc/coredns
        command: ["/coredns", "-conf", "/etc/coredns/Corefile"]
      volumes:
      - name: volume-nfs-coredns
        persistentVolumeClaim:
          claimName: pvc-nfs-coredns
corednsコマンドのオプションについては公式ドキュメントを参照。
coredns.io$ kubectl apply -f coredns-deployment.yaml
deployment.apps/coredns-deployment created
$ kubectl get pods
NAME                                     READY   STATUS    RESTARTS   AGE
coredns-deployment-5bc79b5c88-4bdd5      1/1     Running   0          18s
coredns-deployment-5bc79b5c88-9fn7h      1/1     Running   0          17s
$ kubectl logs coredns-deployment-5bc79b5c88-4bdd5
.:53
[INFO] plugin/reload: Running configuration SHA512 = d433a10a6209646b978eee6a091811a1a8779e9f06a96524a2b55b702985c2f1820f17c5990fc38cb2fc14926f241ee50b07d7fffe3352ef979d98ac74973581
CoreDNS-1.9.3
linux/amd64, go1.18.2, 45b0a11
[root@k8sworker01 ~]# df -t nfs
ファイルシス                              1K-ブロック      使用     使用可 使用% マウント位置
file01:/mnt/data-pool0/nfs/k8s/coredns     2163180544 357269504 1805911040   17% /var/lib/kubelet/pods/2fc83d0c-3884-4eab-b59e-3c5b265821f3/volumes/kubernetes.io~nfs/pv-nfs-coredns
[root@k8sworker01 ~]# ls -l /var/lib/kubelet/pods/2fc83d0c-3884-4eab-b59e-3c5b265821f3/volumes/kubernetes.io~nfs/pv-nfs-coredns
合計 9
-rw-r--r--. 1 root 65533   136  6月  7 23:46 Corefile
-rw-r--r--. 1 root 65533 13147  6月  8 00:05 hosts
Serviceの作成
typeはLoadBalancerとし、ソフトウェアロードバランサであるMetalLBを使用する。
apiVersion: v1
kind: Service
metadata:
  name: coredns-service-tcp
  annotations:
    metallb.universe.tf/allow-shared-ip: "coredns-service-ip"
spec:
  type: LoadBalancer
  loadBalancerIP: 172.16.0.2
  ports:
    - name: tcp
      port: 53
      targetPort: 53
      protocol: TCP
  selector:
    app: coredns
---
apiVersion: v1
kind: Service
metadata:
  name: coredns-service-udp
  annotations:
    metallb.universe.tf/allow-shared-ip: "coredns-service-ip"
spec:
  type: LoadBalancer
  loadBalancerIP: 172.16.0.2
  ports:
    - name: udp
      port: 53
      targetPort: 53
      protocol: UDP
  selector:
    app: coredns
metallb.universe.tf/allow-shared-ipのannotationを設定することで対処する。このannotationを定義しないと、TCPとUDPとで別々のIPアドレスが割り当てられてしまう(loadBalancerIPで固定IPを宣言した場合は、例えばTCPにはIPが割り当てられるがUDPにはPendingになる)。詳細は公式ドキュメントを参照。
metallb.universe.tf$ kubectl apply -f coredns-service-loadbalancer.yaml
service/coredns-service-tcp created
service/coredns-service-udp created
EXTERNAL-IPはTCP/UDPとも172.16.0.2であることが確認できる。$ kubectl get services
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
coredns-service-tcp LoadBalancer 10.99.184.19 172.16.0.2 53:31670/TCP 33s
coredns-service-udp LoadBalancer 10.108.126.55 172.16.0.2 53:31803/UDP 32s
動作確認
$ nslookup.exe k8sctrpln01 172.16.0.2
サーバー:  dns021.tmpdomain.local
Address:  172.16.0.2

名前:    k8sctrpln01
Address:  172.16.0.11
$ kubectl logs -f coredns-deployment-5bc79b5c88-4bdd5
.:53
[INFO] plugin/reload: Running configuration SHA512 = d433a10a6209646b978eee6a091811a1a8779e9f06a96524a2b55b702985c2f1820f17c5990fc38cb2fc14926f241ee50b07d7fffe3352ef979d98ac74973581
CoreDNS-1.9.3
linux/amd64, go1.18.2, 45b0a11
[INFO] 10.244.0.0 is Request: k8sctrpln01. A 5587
あとがき
参考記事
Kubernetes環境でアプリケーションの外部公開をしてみた
nginxコンテナ1つで構成されるPodを2つ作成する。Podの数は任意。 Deploymentを作成する。 Podに割り当てられたIPアドレスを確認する。 このIPアドレスはKubernetesクラスタ内部のものなので、クラスタ外部からのアクセスは通らない。以下はノードと同一ネットワークに所属するWindowsマシンからcurlを実行した例。 クラスタ内部からのアクセスは通る。以下はPod 先に結論だが、この構成ではクラスタ外部にアプリケーションを公開できない。ClusterIPはクラスタ内部からのみアクセス可能。 ClusterIPタイプのServiceを作成する。 クラスタ内部からアクセス可能なClusterIPが割り当てられた。 Endpointsが各PodのIPアドレスとなっている。Serviceにアクセスが来るとkube-proxyによりEndpointsに分散される。 念のためクラスタ外部からはアクセスできないことを確認。 クラスタ内部からはアクセスできる。 未稿 kubernetes.io
metallb.universe.tf クラウド環境においてLoadBalancerタイプのServiceをデプロイすると、クラウド環境上にロードバランサを作成し、クラスタ外部のIPアドレスを割り当ててくれるらしい。 MetalLBのインストール準備をする。 なにやらつまづいている様子。 暫定対処として、 の順に試したが状況変わらず。最終的に ことで解消した。追って必要なポートを調査せねば。 LoadBalancerタイプのServiceを作成する。 クラスタ外部のIPにアクセスできた。 未稿 未稿 LoadBalancerかIngressが実用性がありそう。 kubernetes.io
metallb.universe.tf
blog.framinal.life
blog.yumenomatayume.net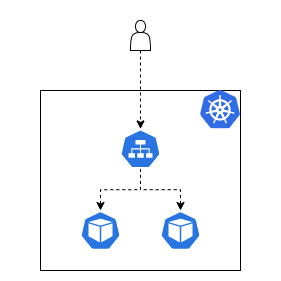
全編目次
概要
環境
構成
ホスト名
IPアドレス
OS
用途
備考
k8sctrpln01
172.16.0.11/24
CentOS 7.9.2009
コントロールプレーンノード
QEMU+KVM仮想ゲスト
k8sworker01
172.16.0.12/24
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
k8sworker02
172.16.0.13/24
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
-
172.16.0.21/24
MetalLB
ソフトウェアロードバランサ
address pool: 172.16.0.21-172.16.0.25/24
client01
172.16.0.100/24
Windows 10
クライアント
CLI: Git Bash
Web UI: Google Chrome
前提
kubectlコマンドの実行は、クライアントマシン(Windows 10)上で行う。Windowsへのkubectlコマンドのインストールは以下を参照。
kubernetes.ioSTEP1 - Podの作成
ソース
概要図
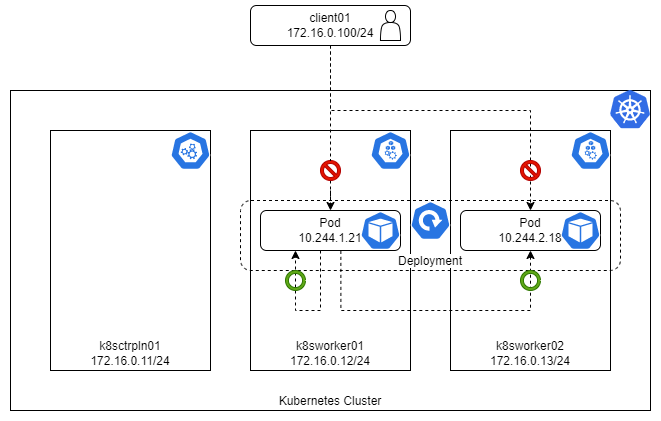
概要
実践
apiVersion: apps/v1
kind: Deployment
metadata:
  name: nginx-deployment
spec:
  selector:
    matchLabels:
      run: nginx
  replicas: 2
  template:
    metadata:
      labels:
        run: nginx
    spec:
      containers:
      - name: nginx
        image: nginx:latest
        ports:
        - containerPort: 80
$ kubectl apply -f nginx-deployment.yaml
deployment.apps/nginx-deployment created
$ kubectl get pods -o wide
NAME                               READY   STATUS    RESTARTS   AGE   IP            NODE
      NOMINATED NODE   READINESS GATES
nginx-deployment-89b88cd64-6dbwl   1/1     Running   0          14s   10.244.1.21   k8sworker01   <none>           <none>
nginx-deployment-89b88cd64-r6mhd   1/1     Running   0          14s   10.244.2.18   k8sworker02   <none>           <none>
※当環境のプロキシが邪魔をしたので--noproxyオプションを使用。$ curl.exe --noproxy "*" -o /dev/null -w '%{http_code}\n' -s http://10.244.1.21:80
000
nginx-deployment-89b88cd64-6dbwlから10.244.1.21、10.244.2.18にcurlを実行した例。$ kubectl exec nginx-deployment-89b88cd64-6dbwl -- curl -o /dev/null -w '%{http_code}\n' -s http://10.244.1.21:80
200
$ kubectl exec nginx-deployment-89b88cd64-6dbwl -- curl -o /dev/null -w '%{http_code}\n' -s http://10.244.2.18:80
200
STEP2 - Serviceの作成
CASE1 - ClusterIPタイプのServiceを使用した構成
ソース
概要図
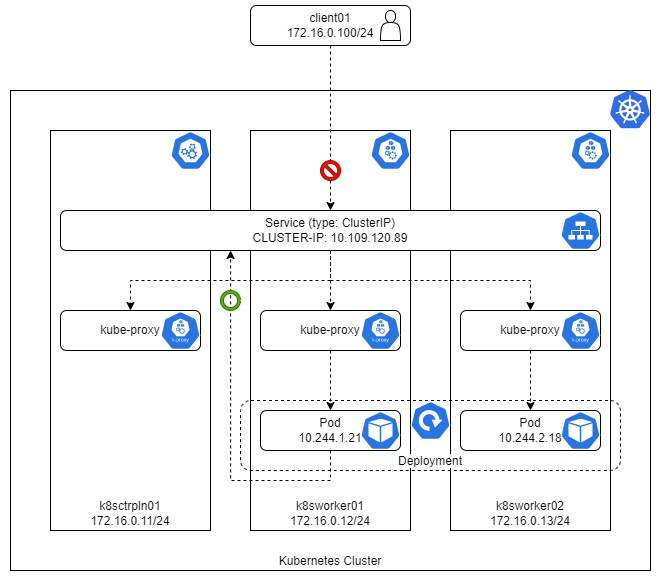
概要
実践
apiVersion: v1
kind: Service
metadata:
  name: nginx-service
  labels:
    run: nginx
spec:
  type: ClusterIP # 公式ドキュメントでは省略している(省略時はClusterIPになる)
  ports:
  - port: 80
    protocol: TCP
  selector:
    run: nginx
$ kubectl apply -f nginx-service-clusterip.yaml
service/nginx-service created
$ kubectl get services nginx-service
NAME            TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)   AGE
nginx-service   ClusterIP   10.109.120.89   <none>        80/TCP    68s
$ kubectl describe services nginx-service
Name:              nginx-service
Namespace:         default
Labels:            run=nginx
Annotations:       <none>
Selector:          run=nginx
Type:              ClusterIP
IP Family Policy:  SingleStack
IP Families:       IPv4
IP:                10.109.120.89
IPs:               10.109.120.89
Port:              <unset>  80/TCP
TargetPort:        80/TCP
Endpoints:         10.244.1.21:80,10.244.2.18:80
Session Affinity:  None
Events:            <none>
$ curl.exe --noproxy "*" -o /dev/null -w '%{http_code}\n' -s http://10.109.120.89:80
000
$ kubectl exec nginx-deployment-89b88cd64-6dbwl -- curl -o /dev/null -w '%{http_code}\n' -s http://10.109.120.89:80
200
CASE2 - NodePortタイプのServiceを使用した構成
CASE3 - LoadBalancerタイプのServiceを使用した構成
ソース
概要図
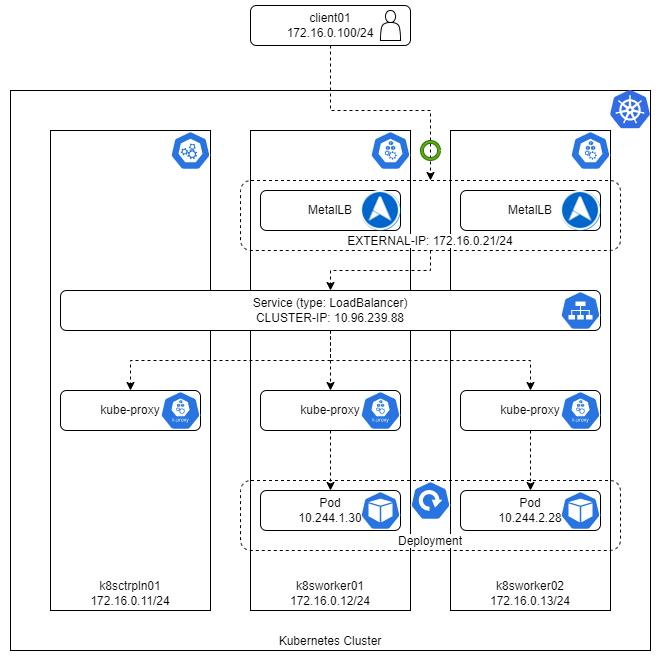
概要
オンプレ環境ではロードバランサの作成処理が進まないため、ソフトウェアロードバランサであるMetalLBをインストールすることで代替することができる。実践
MetalLBの作成
$ kubectl describe configmap -n kube-system kube-proxy | grep strictARP
  strictARP: false
$ kubectl get configmap kube-proxy -n kube-system -o yaml | sed -e "s/strictARP: false/strictARP: true/" | kubectl diff -f - -n kube-system
diff -u -N "C:\\Users\\root\\AppData\\Local\\Temp\\LIVE-1938845299/v1.ConfigMap.kube-system.kube-proxy" "C:\\Users\\root\\AppData\\Local\\Temp\\MERGED-1255996808/v1.ConfigMap.kube-system.kube-proxy"
--- "C:\\Users\\root\\AppData\\Local\\Temp\\LIVE-1938845299/v1.ConfigMap.kube-system.kube-proxy"    2022-06-04 01:33:37.477912900 +0900
+++ "C:\\Users\\root\\AppData\\Local\\Temp\\MERGED-1255996808/v1.ConfigMap.kube-system.kube-proxy"  2022-06-04 01:33:37.479487200 +0900
@@ -33,7 +33,7 @@
       excludeCIDRs: null
       minSyncPeriod: 0s
       scheduler: ""
-      strictARP: false
+      strictARP: true
       syncPeriod: 0s
       tcpFinTimeout: 0s
       tcpTimeout: 0s
@@ -100,9 +100,9 @@
     fieldsV1:
       f:data:
         f:config.conf: {}
-    manager: kubectl-edit
+    manager: kubectl-client-side-apply
     operation: Update
-    time: "2022-06-03T12:03:26Z"
+    time: "2022-06-03T16:33:36Z"
   name: kube-proxy
   namespace: kube-system
   resourceVersion: "667909"
$ kubectl get configmap kube-proxy -n kube-system -o yaml | sed -e "s/strictARP: false/strictARP: true/" | kubectl apply -f - -n kube-system
Warning: resource configmaps/kube-proxy is missing the kubectl.kubernetes.io/last-applied-configuration annotation which is required by kubectl apply. kubectl apply should only be used on resources created declaratively by either kubectl create --save-config or kubectl apply. The missing annotation will be patched automatically.
configmap/kube-proxy configured
$ kubectl describe configmap -n kube-system kube-proxy | grep strictARP
  strictARP: true
$ kubectl apply -f https://raw.githubusercontent.com/metallb/metallb/v0.12.1/manifests/namespace.yaml
namespace/metallb-system created
$ kubectl apply -f https://raw.githubusercontent.com/metallb/metallb/v0.12.1/manifests/metallb.yaml
Warning: policy/v1beta1 PodSecurityPolicy is deprecated in v1.21+, unavailable in v1.25+
podsecuritypolicy.policy/controller created
podsecuritypolicy.policy/speaker created
serviceaccount/controller created
serviceaccount/speaker created
clusterrole.rbac.authorization.k8s.io/metallb-system:controller created
clusterrole.rbac.authorization.k8s.io/metallb-system:speaker created
role.rbac.authorization.k8s.io/config-watcher created
role.rbac.authorization.k8s.io/pod-lister created
role.rbac.authorization.k8s.io/controller created
clusterrolebinding.rbac.authorization.k8s.io/metallb-system:controller created
clusterrolebinding.rbac.authorization.k8s.io/metallb-system:speaker created
rolebinding.rbac.authorization.k8s.io/config-watcher created
rolebinding.rbac.authorization.k8s.io/pod-lister created
rolebinding.rbac.authorization.k8s.io/controller created
daemonset.apps/speaker created
deployment.apps/controller created
$ kubectl -n metallb-system get pods
NAME                          READY   STATUS                       RESTARTS      AGE
controller-7476b58756-dp7hd   0/1     CrashLoopBackOff             1 (12s ago)   18s
speaker-427rt                 0/1     CreateContainerConfigError   0             18s
speaker-mkbcr                 0/1     CreateContainerConfigError   0             18s
$ kubectl -n metallb-system logs controller-7476b58756-dp7hd
{"branch":"HEAD","caller":"level.go:63","commit":"v0.12.1","goversion":"gc / go1.16.14 / amd64","level":"info","msg":"MetalLB controller starting version 0.12.1 (commit v0.12.1, branch HEAD)","ts":"2022-06-04T13:35:16.862838665Z","version":"0.12.1"}
{"caller":"level.go:63","error":"Get \"https://10.96.0.1:443/api/v1/namespaces/metallb-system/secrets?fieldSelector=metadata.name%3Dmemberlist\": dial tcp 10.96.0.1:443: connect: no route to host","level":"error","msg":"failed to create memberlist secret","op":"startup","ts":"2022-06-04T13:35:17.865843229Z"}
dial tcp 10.96.0.1:443: connect: no route to hostとのことで、以下のServiceへの疎通ができていないように見える。$ kubectl get services kubernetes
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
kubernetes ClusterIP 10.96.0.1 <none> 443/TCP 6d3h
$ ssh k8sctrpln03 systemctl stop firewalld
$ ssh k8sworker01 systemctl stop firewalld
$ ssh k8sworker02 systemctl stop firewalld
$ kubectl -n metallb-system get pods
NAME                          READY   STATUS    RESTARTS        AGE
controller-7476b58756-dp7hd   1/1     Running   8 (6m50s ago)   17m
speaker-427rt                 1/1     Running   0               17m
speaker-mkbcr                 1/1     Running   0               17m
apiVersion: v1
kind: ConfigMap
metadata:
  namespace: metallb-system
  name: config
data:
  config: |
    address-pools:
    - name: default
      protocol: layer2
      addresses:
      - 172.16.0.21-172.16.0.25
$ kubectl apply -f metallb-config.yaml
configmap/config created
$ kubectl -n metallb-system get configmap config
NAME     DATA   AGE
config   1      6s
Serviceの作成
apiVersion: v1
kind: Service
metadata:
  name: nginx-service
  labels:
    run: nginx
spec:
  type: LoadBalancer
  ports:
  - port: 80
    protocol: TCP
  selector:
    run: nginx
$ kubectl delete services nginx-service
service "nginx-service" deleted
$ kubectl apply -f nginx-service-loadbalancer.yaml
service/nginx-service created
EXTERNAL-IPが割り当てられている。$ kubectl get services nginx-service
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
nginx-service LoadBalancer 10.96.239.88 172.16.0.21 80:32191/TCP 8s
$ kubectl describe services nginx-service
Name:                     nginx-service
Namespace:                default
Labels:                   run=nginx
Annotations:              <none>
Selector:                 run=nginx
Type:                     LoadBalancer
IP Family Policy:         SingleStack
IP Families:              IPv4
IP:                       10.96.239.88
IPs:                      10.96.239.88
LoadBalancer Ingress:     172.16.0.21
Port:                     <unset>  80/TCP
TargetPort:               80/TCP
NodePort:                 <unset>  32191/TCP
Endpoints:                10.244.1.30:80,10.244.2.28:80
Session Affinity:         None
External Traffic Policy:  Cluster
Events:
  Type    Reason        Age   From                Message
  ----    ------        ----  ----                -------
  Normal  IPAllocated   22s   metallb-controller  Assigned IP ["172.16.0.21"]
  Normal  nodeAssigned  22s   metallb-speaker     announcing from node "k8sworker02"
$ curl.exe --noproxy "*" -o /dev/null -w '%{http_code}\n' -s http://172.16.0.21:80
200
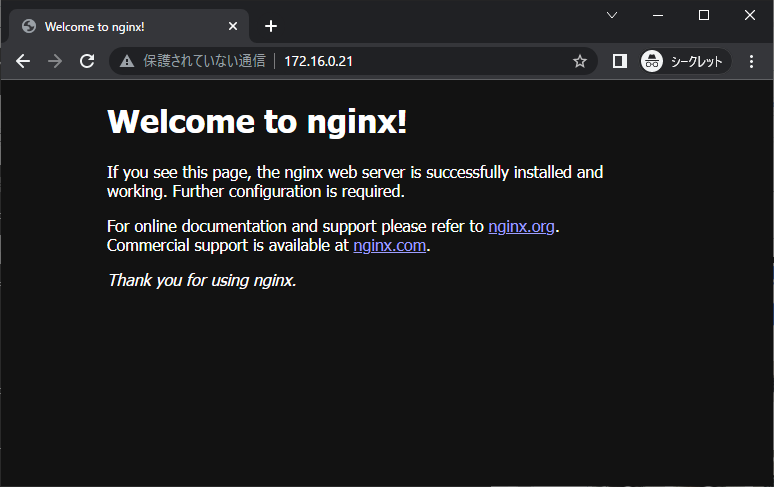 ※アクセスできないこともあったが、Serviceを再作成したらうまくいった。しかしそれは正常とは言えないので、原因を調査する必要がある。
CASE4 - IngressとClusterIPタイプのServiceを使用した構成
CASE5 - ExternalIPsとClusterIPタイプのServiceを使用した構成
あとがき
参考記事
Kubernetes環境を構築してみた
Kubernetes環境を構築する。当記事の範囲はコンテナを載せるための基盤を構築するところまで。 実務経験としてのスキルがオンプレの物理/仮想マシンくらいしかなく、焦りを感じているこの頃。今回はコンテナおよびコンテナオーケストレーションの学習としてKubernetesを触ってみた。 原則として公式ドキュメントに沿って進めていく。
kubernetes.io
※すんなり行くなら二番煎じになるので記事にしないつもりだったが、すんなり行かないから記事にした・・・ コントロールプレーンノードについてのみ確認する。後述するがワーカノードはコントロールプレーンノードを複製して構築する。 インターフェースを1つしか使用しないためルーティングの考慮は不要。 CentOS7はnftablesを導入していないので対象外。 Containerdを選択した。 Dockerとcontainerdの両方が同時に検出された場合、Dockerが優先されます。 の記述があるため、当初はDockerを選択していた。しかし、Kubernetesのバージョンv1.24以降はContainerdが優先される仕様に変わっているらしく、Containerdを選択して再構築した。
github.com 補足だが、気づいたのは 公式ドキュメントでは自動起動の有効化はしていないが、試しに無効のままでOS再起動したら各種サービスが起動しなかったので有効化しておく。 systemdのcgroupドライバーを使うには、/etc/containerd/config.toml内でplugins.cri.systemd_cgroup = trueを設定してください。 kubeadmを使う場合はkubeletのためのcgroupドライバーを手動で設定してください。 後ほど設定する。 GPGチェックが失敗した様子。
github.com この時点ではまだ kubeadmが何をすべきか指示するまで、kubeletはクラッシュループで数秒ごとに再起動します。 次のページへ。 さっき見た。 へい。 さっきやった。 うまくいかない。エラー抜粋。 さらに抜粋。 こちらを参考に
Containerdサービスの起動パラメータにプロキシを設定することで解決した。 が、別のエラーが出た。抜粋。 まずは自力で調査。Containerdサービスは起動している。 しかし、Containerdのユーティリティである WARNはendpointを指定することで回避できたが、エラーは解消せず。 ググると ※ 本題に戻り コントロールプレーンノードをクラスタ構成にする場合は対処が必要。今回はシングルノード構成なのでスキップ。 Podネットワークアドオンが未インストールの状態だと、corednsが アドオンはいくつかあるが、とくに根拠も無くflannelを使用する。
入手先のURLは 以下にたどり着く。
github.com
ここでもプロキシの壁が。 改めてインストール。 まずkube-flannelの状態が kube-flannelのPodのログを確認する。 flannnelが通信するインターフェースを自動検出する処理が、 切り分けとして手元にあった古いバージョンの なお、この時点でコントロールプレーンノードが Podはワーカノードのみで起動させたいので対象外。 当環境のノードは仮想ゲストマシンのため、コントロールプレーンノードからワーカノードを複製し、ワーカノード向けに設定変更する方式で構築する。 Kubernetes環境を初期化する。 手動でのクリーンアップも必要。 ワーカノード用にファイアウォールを設定する。 コントロールプレーンノードで ワーカノードがクラスタに参加できたことを確認する。 せっかくなのでワーカノードをもう1台参加させた。 おまけ。 とりあえずスキップ。 とりあえずスキップ。 原則不要。環境再構築時など必要に応じて。 見たところ必須ではなさそう。 構築は2回目だったが、半日程度かかった。 本文中に記載。
全編目次
概要
経緯
環境
概要図
※赤い箇所が当記事で扱う範囲。構成
ホスト名
IPアドレス
OS
用途
備考
k8sctrpln01
172.16.0.11
CentOS 7.9.2009
コントロールプレーンノード
QEMU+KVM仮想ゲスト
k8sworker01
172.16.0.12
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
k8sworker02
172.16.0.13
CentOS 7.9.2009
ワーカノード
QEMU+KVM仮想ゲスト
dns01
172.16.0.1
CentOS 8.5.2111
DNSサーバ
QEMU+KVM仮想ゲスト
dns02
172.16.0.2
coredns/coredns
DNSサーバ
コンテナサービス
proxy01
172.16.0.3
CentOS 8.5.2111
プロキシサーバ
QEMU+KVM仮想ゲスト
前提
構築
kubeadmのインストール
始める前に
[root@k8sctrpln01 ~]# cat /etc/redhat-release
CentOS Linux release 7.9.2009 (Core)
[root@k8sctrpln01 ~]# free -h
              total        used        free      shared  buff/cache   available
Mem:           2.0G        128M        1.7G        8.6M        123M        1.7G
Swap:          2.0G          0B        2.0G
[root@k8sctrpln01 ~]# cat /proc/cpuinfo | grep processor
processor       : 0
processor       : 1
[root@k8sctrpln01 ~]# swapon -s
Filename                                Type            Size    Used    Priority
/dev/vda2                               partition       2097148 0       -2
[root@k8sctrpln01 ~]# swapoff -a
[root@k8sctrpln01 ~]# swapon -s
[root@k8sctrpln01 ~]# cp -p /etc/fstab{,_`date +%Y%m%d`}
[root@k8sctrpln01 ~]# ls -l /etc/fstab*
-rw-r--r--. 1 root root 501  2月 26  2020 /etc/fstab
-rw-r--r--  1 root root 501  2月 26  2020 /etc/fstab_20220529
[root@k8sctrpln01 ~]# sed -i /swap/s/^/#/g /etc/fstab
[root@k8sctrpln01 ~]# diff /etc/fstab{,_`date +%Y%m%d`}
11c11
< #UUID=ea60423d-e182-4843-a7fa-393d738a20d1 swap                    swap    defaults        0 0
---
> UUID=ea60423d-e182-4843-a7fa-393d738a20d1 swap                    swap    defaults        0 0
MACアドレスとproduct_uuidが全てのノードでユニークであることの検証
[root@k8sctrpln01 ~]# uname -n
k8sctrpln01
[root@k8sctrpln01 ~]# ip link
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN mode DEFAULT group default qlen 1000
    link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:f9:d5:4d brd ff:ff:ff:ff:ff:ff
3: eth1: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:25:ca:02 brd ff:ff:ff:ff:ff:ff
4: eth2: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:15:69:ca brd ff:ff:ff:ff:ff:ff
[root@k8sctrpln01 ~]# cat /sys/class/dmi/id/product_uuid
BB935834-A266-4B61-A591-4589BFE06A62
ネットワークアダプタの確認
iptablesがブリッジを通過するトラフィックを処理できるようにする
[root@k8sctrpln01 ~]# lsmod | grep ^br_netfilter
[root@k8sctrpln01 ~]# modprobe br_netfilter
[root@k8sctrpln01 ~]# lsmod | grep ^br_netfilter
br_netfilter           22256  0
[root@k8sctrpln01 ~]# sysctl -n net.bridge.bridge-nf-call-ip6tables -n net.bridge.bridge-nf-call-iptables
1
1
[root@k8sctrpln01 ~]# cat <<EOF > /etc/sysctl.d/k8s.conf
> net.bridge.bridge-nf-call-ip6tables = 1
> net.bridge.bridge-nf-call-iptables = 1
> EOF
[root@k8sctrpln01 ~]# sysctl --system
* Applying /usr/lib/sysctl.d/00-system.conf ...
net.bridge.bridge-nf-call-ip6tables = 0
net.bridge.bridge-nf-call-iptables = 0
net.bridge.bridge-nf-call-arptables = 0
* Applying /usr/lib/sysctl.d/10-default-yama-scope.conf ...
kernel.yama.ptrace_scope = 0
* Applying /usr/lib/sysctl.d/50-default.conf ...
kernel.sysrq = 16
kernel.core_uses_pid = 1
kernel.kptr_restrict = 1
net.ipv4.conf.default.rp_filter = 1
net.ipv4.conf.all.rp_filter = 1
net.ipv4.conf.default.accept_source_route = 0
net.ipv4.conf.all.accept_source_route = 0
net.ipv4.conf.default.promote_secondaries = 1
net.ipv4.conf.all.promote_secondaries = 1
fs.protected_hardlinks = 1
fs.protected_symlinks = 1
* Applying /etc/sysctl.d/99-sysctl.conf ...
* Applying /etc/sysctl.d/disable_ipv6.conf ...
net.ipv6.conf.all.disable_ipv6 = 1
* Applying /etc/sysctl.d/k8s.conf ...
net.bridge.bridge-nf-call-ip6tables = 1
net.bridge.bridge-nf-call-iptables = 1
* Applying /etc/sysctl.conf ...
[root@k8sctrpln01 ~]# sysctl -n net.bridge.bridge-nf-call-ip6tables -n net.bridge.bridge-nf-call-iptables
1
1
iptablesがnftablesバックエンドを使用しないようにする
必須ポートの確認
[root@k8sctrpln01 ~]# grep -R -e 6443 -e 2379 -e 2380 -e 10250 -e 10251 -e 10252 /lib/firewalld/services/
/lib/firewalld/services/etcd-client.xml:  <port port="2379" protocol="tcp"/>
/lib/firewalld/services/etcd-server.xml:  <port port="2380" protocol="tcp"/>
[root@k8sctrpln01 ~]# firewall-cmd --list-services
dhcpv6-client snmp ssh
[root@k8sctrpln01 ~]# firewall-cmd --list-ports
[root@k8sctrpln01 ~]# firewall-cmd --add-service={etcd-client,etcd-server} --permanent
success
[root@k8sctrpln01 ~]# firewall-cmd --add-port={6443/tcp,10250/tcp,10251/tcp,10252/tcp} --permanent
success
[root@k8sctrpln01 ~]# firewall-cmd --reload
success
[root@k8sctrpln01 ~]# firewall-cmd --list-services
dhcpv6-client etcd-client etcd-server snmp ssh
[root@k8sctrpln01 ~]# firewall-cmd --list-ports
6443/tcp 10250/tcp 10251/tcp 10252/tcp
ランタイムのインストール
実は、公式ドキュメントにkubeadm initのトラブルシューティング中。公式ドキュメントが追い付いていないので事前に気づけない。[root@k8sctrpln01 ~]# kubeadm init --pod-network-cidr 10.244.0.0/16 --v=5
I0528 00:23:59.899926 26554 initconfiguration.go:117] detected and using CRI socket: unix:///var/run/containerd/containerd.sock
Containerd
必要な設定の追加
[root@k8sctrpln01 ~]# cat > /etc/modules-load.d/containerd.conf <<EOF
> overlay
> br_netfilter
> EOF
[root@k8sctrpln01 ~]# lsmod | grep -e ^overlay -e ^br_netfilter
br_netfilter           22256  0
[root@k8sctrpln01 ~]# modprobe overlay
[root@k8sctrpln01 ~]# modprobe br_netfilter
[root@k8sctrpln01 ~]# lsmod | grep -e ^overlay -e ^br_netfilter
overlay                91659  0
br_netfilter           22256  0
[root@k8sctrpln01 ~]# cat > /etc/sysctl.d/99-kubernetes-cri.conf <<EOF
> net.bridge.bridge-nf-call-iptables  = 1
> net.ipv4.ip_forward                 = 1
> net.bridge.bridge-nf-call-ip6tables = 1
> EOF
[root@k8sctrpln01 ~]# sysctl -n net.bridge.bridge-nf-call-iptables -n net.ipv4.ip_forward -n net.bridge.bridge-nf-call-ip6tables
1
0
1
[root@k8sctrpln01 ~]# sysctl --system
* Applying /usr/lib/sysctl.d/00-system.conf ...
net.bridge.bridge-nf-call-ip6tables = 0
net.bridge.bridge-nf-call-iptables = 0
net.bridge.bridge-nf-call-arptables = 0
* Applying /usr/lib/sysctl.d/10-default-yama-scope.conf ...
kernel.yama.ptrace_scope = 0
* Applying /usr/lib/sysctl.d/50-default.conf ...
kernel.sysrq = 16
kernel.core_uses_pid = 1
kernel.kptr_restrict = 1
net.ipv4.conf.default.rp_filter = 1
net.ipv4.conf.all.rp_filter = 1
net.ipv4.conf.default.accept_source_route = 0
net.ipv4.conf.all.accept_source_route = 0
net.ipv4.conf.default.promote_secondaries = 1
net.ipv4.conf.all.promote_secondaries = 1
fs.protected_hardlinks = 1
fs.protected_symlinks = 1
* Applying /etc/sysctl.d/99-kubernetes-cri.conf ...
net.bridge.bridge-nf-call-iptables = 1
net.ipv4.ip_forward = 1
net.bridge.bridge-nf-call-ip6tables = 1
* Applying /etc/sysctl.d/99-sysctl.conf ...
* Applying /etc/sysctl.d/disable_ipv6.conf ...
net.ipv6.conf.all.disable_ipv6 = 1
* Applying /etc/sysctl.d/k8s.conf ...
net.bridge.bridge-nf-call-ip6tables = 1
net.bridge.bridge-nf-call-iptables = 1
* Applying /etc/sysctl.conf ...
[root@k8sctrpln01 ~]# sysctl -n net.bridge.bridge-nf-call-iptables -n net.ipv4.ip_forward -n net.bridge.bridge-nf-call-ip6tables
1
1
1
containerdのインストール
[root@k8sctrpln01 ~]# yum install -y yum-utils device-mapper-persistent-data lvm2
---snip---
[root@k8sctrpln01 ~]# yum list installed -q yum-utils device-mapper-persistent-data lvm2
インストール済みパッケージ
device-mapper-persistent-data.x86_64                          0.8.5-3.el7_9.2                                @updates
lvm2.x86_64                                                   7:2.02.187-6.el7_9.5                           @updates
yum-utils.noarch                                              1.1.31-54.el7_8                                @base
[root@k8sctrpln01 ~]# yum-config-manager --add-repo https://download.docker.com/linux/centos/docker-ce.repo
読み込んだプラグイン:fastestmirror
adding repo from: https://download.docker.com/linux/centos/docker-ce.repo
grabbing file https://download.docker.com/linux/centos/docker-ce.repo to /etc/yum.repos.d/docker-ce.repo
repo saved to /etc/yum.repos.d/docker-ce.repo
[root@k8sctrpln01 ~]# yum update -y
---snip---
[root@k8sctrpln01 ~]# yum install -y containerd.io
---snip---
[root@k8sctrpln01 ~]# yum list -q containerd.io
インストール済みパッケージ
containerd.io.x86_64                                 1.6.4-3.1.el7                                  @docker-ce-stable
[root@k8sctrpln01 ~]# mkdir -p /etc/containerd
[root@k8sctrpln01 ~]# mv /etc/containerd/config.toml /etc/containerd/config.toml_org
[root@k8sctrpln01 ~]# containerd config default > /etc/containerd/config.toml
[root@k8sctrpln01 ~]# systemctl restart containerd
[root@k8sctrpln01 ~]# systemctl is-active containerd
active
[root@k8sctrpln01 ~]# systemctl is-enabled containerd
disabled
[root@k8sctrpln01 ~]# systemctl enable containerd
Created symlink from /etc/systemd/system/multi-user.target.wants/containerd.service to /usr/lib/systemd/system/containerd.service.
[root@k8sctrpln01 ~]# systemctl is-enabled containerd
enabled
systemd
plugins.cri.systemd_cgroupでgrepしても見つからなくて、どこのセクションに書けば良いかわからず困ったが、以下の構造らしい。わからんわ。[root@k8sctrpln01 ~]# cat -n /etc/containerd/config.toml | grep systemd_cgroup
67 systemd_cgroup = false
[root@k8sctrpln01 ~]# cat -n /etc/containerd/config.toml
---snip---
    45    [plugins."io.containerd.grpc.v1.cri"]
    46      device_ownership_from_security_context = false
    47      disable_apparmor = false
    48      disable_cgroup = false
    49      disable_hugetlb_controller = true
    50      disable_proc_mount = false
    51      disable_tcp_service = true
    52      enable_selinux = false
    53      enable_tls_streaming = false
    54      enable_unprivileged_icmp = false
    55      enable_unprivileged_ports = false
    56      ignore_image_defined_volumes = false
    57      max_concurrent_downloads = 3
    58      max_container_log_line_size = 16384
    59      netns_mounts_under_state_dir = false
    60      restrict_oom_score_adj = false
    61      sandbox_image = "k8s.gcr.io/pause:3.6"
    62      selinux_category_range = 1024
    63      stats_collect_period = 10
    64      stream_idle_timeout = "4h0m0s"
    65      stream_server_address = "127.0.0.1"
    66      stream_server_port = "0"
    67      systemd_cgroup = false
    68      tolerate_missing_hugetlb_controller = true
    69      unset_seccomp_profile = ""
---snip---
[root@k8sctrpln01 ~]# sed -i 's/systemd_cgroup = false/systemd_cgroup = true/g' /etc/containerd/config.toml
[root@k8sctrpln01 ~]# cat -n /etc/containerd/config.toml | grep systemd_cgroup
    67      systemd_cgroup = true
kubeadm、kubelet、kubectlのインストール
[root@k8sctrpln01 ~]# cat <<EOF > /etc/yum.repos.d/kubernetes.repo
> [kubernetes]
> name=Kubernetes
> baseurl=https://packages.cloud.google.com/yum/repos/kubernetes-el7-x86_64
> enabled=1
> gpgcheck=1
> repo_gpgcheck=1
> gpgkey=https://packages.cloud.google.com/yum/doc/yum-key.gpg https://packages.cloud.google.com/yum/doc/rpm-package-key.gpg
> EOF
[root@k8sctrpln01 ~]# setenforce 0
[root@k8sctrpln01 ~]# getenforce
Permissive
[root@k8sctrpln01 ~]# sed -i '/^SELINUX=/s/.*/SELINUX=permissive/' /etc/selinux/config
[root@k8sctrpln01 ~]# grep "^SELINUX=" /etc/selinux/config
SELINUX=permissive
[root@k8sctrpln01 ~]# yum install -y kubelet kubeadm kubectl --disableexcludes=kubernetes
読み込んだプラグイン:fastestmirror
Loading mirror speeds from cached hostfile
 * base: ftp.iij.ad.jp
 * extras: ftp.iij.ad.jp
 * updates: ftp.iij.ad.jp
base                                                                                          | 3.6 kB  00:00:00
extras                                                                                        | 2.9 kB  00:00:00
kubernetes/signature                                                                          |  844 B  00:00:00
https://packages.cloud.google.com/yum/doc/yum-key.gpg から鍵を取得中です。
Importing GPG key 0x6B4097C2:
 Userid     : "Rapture Automatic Signing Key (cloud-rapture-signing-key-2022-03-07-08_01_01.pub)"
 Fingerprint: e936 7157 4236 81a4 7ec3 93c3 7325 816a 6b40 97c2
 From       : https://packages.cloud.google.com/yum/doc/yum-key.gpg
https://packages.cloud.google.com/yum/doc/rpm-package-key.gpg から鍵を取得中です。
kubernetes/signature                                                                          | 1.4 kB  00:00:00 !!!
https://packages.cloud.google.com/yum/repos/kubernetes-el7-x86_64/repodata/repomd.xml: [Errno -1] repomd.xml signature could not be verified for kubernetes
他のミラーを試します。


 One of the configured repositories failed (Kubernetes),
 and yum doesn't have enough cached data to continue. At this point the only
 safe thing yum can do is fail. There are a few ways to work "fix" this:

     1. Contact the upstream for the repository and get them to fix the problem.

     2. Reconfigure the baseurl/etc. for the repository, to point to a working
        upstream. This is most often useful if you are using a newer
        distribution release than is supported by the repository (and the
        packages for the previous distribution release still work).

     3. Run the command with the repository temporarily disabled
            yum --disablerepo=kubernetes ...

     4. Disable the repository permanently, so yum won't use it by default. Yum
        will then just ignore the repository until you permanently enable it
        again or use --enablerepo for temporary usage:

            yum-config-manager --disable kubernetes
        or
            subscription-manager repos --disable=kubernetes

     5. Configure the failing repository to be skipped, if it is unavailable.
        Note that yum will try to contact the repo. when it runs most commands,
        so will have to try and fail each time (and thus. yum will be be much
        slower). If it is a very temporary problem though, this is often a nice
        compromise:

            yum-config-manager --save --setopt=kubernetes.skip_if_unavailable=true

failure: repodata/repomd.xml from kubernetes: [Errno 256] No more mirrors to try.
https://packages.cloud.google.com/yum/repos/kubernetes-el7-x86_64/repodata/repomd.xml: [Errno -1] repomd.xml signature could not be verified for kubernetes
repo_gpgcheck=0でチェックをスキップする。[root@k8sctrpln01 ~]# sed -i 's/^repo_gpgcheck=1/repo_gpgcheck=0/g' /etc/yum.repos.d/kubernetes.repo
[root@k8sctrpln01 ~]# yum install -y kubelet kubeadm kubectl --disableexcludes=kubernetes
[root@k8sctrpln01 ~]# yum list -q kubelet kubeadm kubectl
インストール済みパッケージ
kubeadm.x86_64                                          1.24.1-0                                          @kubernetes
kubectl.x86_64                                          1.24.1-0                                          @kubernetes
kubelet.x86_64                                          1.24.1-0                                          @kubernetes
[root@k8sctrpln01 ~]# systemctl enable --now kubelet
Created symlink from /etc/systemd/system/multi-user.target.wants/kubelet.service to /usr/lib/systemd/system/kubelet.service.
[root@k8sctrpln01 ~]# systemctl is-enabled kubelet
enabled
[root@k8sctrpln01 ~]# systemctl is-active kubelet
activating
activeにならなくて正しい。コントロールプレーンノードのkubeletによって使用されるcgroupドライバーの設定
[root@k8sctrpln01 ~]# cat /etc/sysconfig/kubelet
KUBELET_EXTRA_ARGS=
[root@k8sctrpln01 ~]# sed -i "s/^KUBELET_EXTRA_ARGS=/KUBELET_EXTRA_ARGS=--cgroup-driver=systemd/g" /etc/sysconfig/kubelet
[root@k8sctrpln01 ~]# cat /etc/sysconfig/kubelet
KUBELET_EXTRA_ARGS=--cgroup-driver=systemd
[root@k8sctrpln01 ~]# systemctl daemon-reload
[root@k8sctrpln01 ~]# systemctl restart kubelet
次の項目
kubeadmを使用したクラスターの作成
始める前に
目的
手順
ホストへのkubeadmのインストール
コントロールプレーンノードの初期化
[root@k8sctrpln01 ~]# kubeadm init --pod-network-cidr 10.244.0.0/16
W0529 05:32:54.020100   15143 version.go:103] could not fetch a Kubernetes version from the internet: unable to get URL "https://dl.k8s.io/release/stable-1.txt": Get "https://dl.k8s.io/release/stable-1.txt": dial tcp: lookup dl.k8s.io on 172.16.0.2:53: server misbehaving
W0529 05:32:54.020248   15143 version.go:104] falling back to the local client version: v1.24.1
[init] Using Kubernetes version: v1.24.1
[preflight] Running pre-flight checks
        [WARNING Firewalld]: firewalld is active, please ensure ports [6443 10250] are open or your cluster may not function correctly
[preflight] Pulling images required for setting up a Kubernetes cluster
[preflight] This might take a minute or two, depending on the speed of your internet connection
[preflight] You can also perform this action in beforehand using 'kubeadm config images pull'
error execution phase preflight: [preflight] Some fatal errors occurred:
        [ERROR ImagePull]: failed to pull image k8s.gcr.io/kube-apiserver:v1.24.1: output: E0529 05:32:55.259199   15185 remote_image.go:238] "PullImage from image service failed" err="rpc error: code = Unknown desc = failed to pull and unpack image \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to resolve reference \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to do request: Head \"https://k8s.gcr.io/v2/kube-apiserver/manifests/v1.24.1\": dial tcp: lookup k8s.gcr.io on 172.16.0.2:53: server misbehaving" image="k8s.gcr.io/kube-apiserver:v1.24.1"
time="2022-05-29T05:32:55+09:00" level=fatal msg="pulling image: rpc error: code = Unknown desc = failed to pull and unpack image \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to resolve reference \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to do request: Head \"https://k8s.gcr.io/v2/kube-apiserver/manifests/v1.24.1\": dial tcp: lookup k8s.gcr.io on 172.16.0.2:53: server misbehaving"
, error: exit status 1
---snip---
[preflight] If you know what you are doing, you can make a check non-fatal with `--ignore-preflight-errors=...`
To see the stack trace of this error execute with --v=5 or higher
[ERROR ImagePull]: failed to pull image k8s.gcr.io/kube-apiserver:v1.24.1: output: E0529 05:32:55.259199 15185 remote_image.go:238] "PullImage from image service failed" err="rpc error: code = Unknown desc = failed to pull and unpack image \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to resolve reference \"k8s.gcr.io/kube-apiserver:v1.24.1\": failed to do request: Head \"https://k8s.gcr.io/v2/kube-apiserver/manifests/v1.24.1\": dial tcp: lookup k8s.gcr.io on 172.16.0.2:53: server misbehaving" image="k8s.gcr.io/kube-apiserver:v1.24.1"
dial tcp: lookup k8s.gcr.io on 172.16.0.2:53: server misbehaving
k8s.gcr.ioの名前解決に失敗している。
原因はプロキシの設定不足。当環境はプロキシサーバを経由してインターネットにアクセスする構成のため、設定が必要だった。[root@k8sctrpln01 ~]# mkdir /etc/systemd/system/containerd.service.d
[root@k8sctrpln01 ~]# cat <<EOF > /etc/systemd/system/containerd.service.d/http-proxy.conf
[Service]
Environment='HTTP_PROXY=http://proxy01:3128'
Environment='HTTPS_PROXY=http://proxy01:3128'
EOF
[root@k8sctrpln01 ~]# systemctl daemon-reload
[root@k8sctrpln01 ~]# systemctl restart containerd
[root@k8sctrpln01 ~]# kubeadm init --pod-network-cidr 10.244.0.0/16
W0529 06:12:34.627517   17351 version.go:103] could not fetch a Kubernetes version from the internet: unable to get URL "https://dl.k8s.io/release/stable-1.txt": Get "https://dl.k8s.io/release/stable-1.txt": dial tcp: lookup dl.k8s.io on 172.16.0.2:53: server misbehaving
W0529 06:12:34.627588   17351 version.go:104] falling back to the local client version: v1.24.1
[init] Using Kubernetes version: v1.24.1
[preflight] Running pre-flight checks
        [WARNING Firewalld]: firewalld is active, please ensure ports [6443 10250] are open or your cluster may not function correctly
error execution phase preflight: [preflight] Some fatal errors occurred:
        [ERROR CRI]: container runtime is not running: output: E0529 06:12:34.648929   17359 remote_runtime.go:925] "Status from runtime service failed" err="rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService"
time="2022-05-29T06:12:34+09:00" level=fatal msg="getting status of runtime: rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService"
, error: exit status 1
[preflight] If you know what you are doing, you can make a check non-fatal with `--ignore-preflight-errors=...`
To see the stack trace of this error execute with --v=5 or higher
[ERROR CRI]: container runtime is not running: output: E0529 06:12:34.648929 17359 remote_runtime.go:925] "Status from runtime service failed" err="rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService"
[root@k8sctrpln01 ~]# systemctl is-active containerd
active
crictlコマンドが使えない。[root@k8sctrpln01 ~]# crictl version
WARN[0000] runtime connect using default endpoints: [unix:///var/run/dockershim.sock unix:///run/containerd/containerd.sock unix:///run/crio/crio.sock unix:///var/run/cri-dockerd.sock]. As the default settings are now deprecated, you should set the endpoint instead.
ERRO[0000] unable to determine runtime API version: rpc error: code = Unavailable desc = connection error: desc = "transport: Error while dialing dial unix /var/run/dockershim.sock: connect: no such file or directory"
E0529 06:36:10.222225 18569 remote_runtime.go:168] "Version from runtime service failed" err="rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService"
FATA[0000] getting the runtime version: rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService
[root@k8sctrpln01 ~]# crictl --runtime-endpoint unix:///run/containerd/containerd.sock version
E0529 06:36:44.521051   18602 remote_runtime.go:168] "Version from runtime service failed" err="rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService"
FATA[0000] getting the runtime version: rpc error: code = Unimplemented desc = unknown service runtime.v1alpha2.RuntimeService
/etc/containerd/config.tomlを削除すれば良い的な記事が見つかった。解せないが他に対処方法も見つからないため、実施する。
github.com[root@k8sctrpln01 ~]# rm /etc/containerd/config.toml
rm: 通常ファイル `/etc/containerd/config.toml' を削除しますか? y
[root@k8sctrpln01 ~]# systemctl restart containerd
[root@k8sctrpln01 ~]# systemctl is-active containerd
active
crictlコマンドが使えるようになった。[root@k8sctrpln01 ~]# crictl --runtime-endpoint unix:///run/containerd/containerd.sock version
Version: 0.1.0
RuntimeName: containerd
RuntimeVersion: 1.6.4
RuntimeApiVersion: v1
/etc/containerd/config.tomlにわざわざsystemd_cgroup = trueを設定したが、あればなんだったのか・・・kubeadm initをリトライ。ようやく突破した。[root@k8sctrpln01 ~]# kubeadm init --pod-network-cidr 10.244.0.0/16
W0529 07:07:11.390743 20256 version.go:103] could not fetch a Kubernetes version from the internet: unable to get URL "https://dl.k8s.io/release/stable-1.txt": Get "https://dl.k8s.io/release/stable-1.txt": dial tcp: lookup dl.k8s.io on 172.16.0.2:53: server misbehaving
W0529 07:07:11.390884 20256 version.go:104] falling back to the local client version: v1.24.1
[init] Using Kubernetes version: v1.24.1
[preflight] Running pre-flight checks
[WARNING Firewalld]: firewalld is active, please ensure ports [6443 10250] are open or your cluster may not function correctly
[preflight] Pulling images required for setting up a Kubernetes cluster
[preflight] This might take a minute or two, depending on the speed of your internet connection
[preflight] You can also perform this action in beforehand using 'kubeadm config images pull'
[certs] Using certificateDir folder "/etc/kubernetes/pki"
[certs] Generating "ca" certificate and key
[certs] Generating "apiserver" certificate and key
[certs] apiserver serving cert is signed for DNS names [k8sctrpln01 kubernetes kubernetes.default kubernetes.default.svc kubernetes.default.svc.cluster.local] and IPs [10.96.0.1 172.16.0.11]
[certs] Generating "apiserver-kubelet-client" certificate and key
[certs] Generating "front-proxy-ca" certificate and key
[certs] Generating "front-proxy-client" certificate and key
[certs] Generating "etcd/ca" certificate and key
[certs] Generating "etcd/server" certificate and key
[certs] etcd/server serving cert is signed for DNS names [k8sctrpln01 localhost] and IPs [172.16.0.11 127.0.0.1 ::1]
[certs] Generating "etcd/peer" certificate and key
[certs] etcd/peer serving cert is signed for DNS names [k8sctrpln01 localhost] and IPs [172.16.0.11 127.0.0.1 ::1]
[certs] Generating "etcd/healthcheck-client" certificate and key
[certs] Generating "apiserver-etcd-client" certificate and key
[certs] Generating "sa" key and public key
[kubeconfig] Using kubeconfig folder "/etc/kubernetes"
[kubeconfig] Writing "admin.conf" kubeconfig file
[kubeconfig] Writing "kubelet.conf" kubeconfig file
[kubeconfig] Writing "controller-manager.conf" kubeconfig file
[kubeconfig] Writing "scheduler.conf" kubeconfig file
[kubelet-start] Writing kubelet environment file with flags to file "/var/lib/kubelet/kubeadm-flags.env"
[kubelet-start] Writing kubelet configuration to file "/var/lib/kubelet/config.yaml"
[kubelet-start] Starting the kubelet
[control-plane] Using manifest folder "/etc/kubernetes/manifests"
[control-plane] Creating static Pod manifest for "kube-apiserver"
[control-plane] Creating static Pod manifest for "kube-controller-manager"
[control-plane] Creating static Pod manifest for "kube-scheduler"
[etcd] Creating static Pod manifest for local etcd in "/etc/kubernetes/manifests"
[wait-control-plane] Waiting for the kubelet to boot up the control plane as static Pods from directory "/etc/kubernetes/manifests". This can take up to 4m0s
[apiclient] All control plane components are healthy after 39.505506 seconds
[upload-config] Storing the configuration used in ConfigMap "kubeadm-config" in the "kube-system" Namespace
[kubelet] Creating a ConfigMap "kubelet-config" in namespace kube-system with the configuration for the kubelets in the cluster
[kubelet-check] Initial timeout of 40s passed.
[upload-certs] Skipping phase. Please see --upload-certs
[mark-control-plane] Marking the node k8sctrpln01 as control-plane by adding the labels: [node-role.kubernetes.io/control-plane node.kubernetes.io/exclude-from-external-load-balancers]
[mark-control-plane] Marking the node k8sctrpln01 as control-plane by adding the taints [node-role.kubernetes.io/master:NoSchedule node-role.kubernetes.io/control-plane:NoSchedule]
[bootstrap-token] Using token: 1alk8n.8haf7p9cszxh2kw1
[bootstrap-token] Configuring bootstrap tokens, cluster-info ConfigMap, RBAC Roles
[bootstrap-token] Configured RBAC rules to allow Node Bootstrap tokens to get nodes
[bootstrap-token] Configured RBAC rules to allow Node Bootstrap tokens to post CSRs in order for nodes to get long term certificate credentials
[bootstrap-token] Configured RBAC rules to allow the csrapprover controller automatically approve CSRs from a Node Bootstrap Token
[bootstrap-token] Configured RBAC rules to allow certificate rotation for all node client certificates in the cluster
[bootstrap-token] Creating the "cluster-info" ConfigMap in the "kube-public" namespace
[kubelet-finalize] Updating "/etc/kubernetes/kubelet.conf" to point to a rotatable kubelet client certificate and key
[addons] Applied essential addon: CoreDNS
[addons] Applied essential addon: kube-proxy
Your Kubernetes control-plane has initialized successfully!
To start using your cluster, you need to run the following as a regular user:
mkdir -p $HOME/.kube
sudo cp -i /etc/kubernetes/admin.conf $HOME/.kube/config
sudo chown $(id -u):$(id -g) $HOME/.kube/config
Alternatively, if you are the root user, you can run:
export KUBECONFIG=/etc/kubernetes/admin.conf
You should now deploy a pod network to the cluster.
Run "kubectl apply -f [podnetwork].yaml" with one of the options listed at:
  https://kubernetes.io/docs/concepts/cluster-administration/addons/
Then you can join any number of worker nodes by running the following on each as root:
kubeadm join 172.16.0.11:6443 --token 1alk8n.8haf7p9cszxh2kw1 \
--discovery-token-ca-cert-hash sha256:fc839a2ff1689c9af8f302670a51c1c44e5a16b7d89304931b7cc9052a192caf
apiserver-advertise-addressとControlPlaneEndpointに関する検討
詳細な情報
[root@k8sctrpln01 ~]# mkdir -p $HOME/.kube
[root@k8sctrpln01 ~]# sudo cp -i /etc/kubernetes/admin.conf $HOME/.kube/config
[root@k8sctrpln01 ~]# sudo chown $(id -u):$(id -g) $HOME/.kube/config
[root@k8sctrpln01 ~]# export KUBECONFIG=/etc/kubernetes/admin.conf
Podネットワークアドオンのインストール
Pending状態のままになっている。[root@k8sctrpln01 ~]# kubectl get pods --all-namespaces
NAMESPACE NAME READY STATUS RESTARTS AGE
kube-system coredns-6d4b75cb6d-66hl2 0/1 Pending 0 3m1s
kube-system coredns-6d4b75cb6d-vnw7j 0/1 Pending 0 3m1s
kube-system etcd-k8sctrpln01 1/1 Running 0 3m30s
kube-system kube-apiserver-k8sctrpln01 1/1 Running 0 3m16s
kube-system kube-controller-manager-k8sctrpln01 1/1 Running 0 3m31s
kube-system kube-proxy-cktd6 1/1 Running 0 3m1s
kube-system kube-scheduler-k8sctrpln01 1/1 Running 0 3m30s
kubeadm initの標準出力に記載されている(普通に見逃す)。さらに、後述するが、flannelのバージョンが最新のv0.18.0では正常動作せず、v0.16.3を使用した。You should now deploy a pod network to the cluster.
Run "kubectl apply -f [podnetwork].yaml" with one of the options listed at:
https://kubernetes.io/docs/concepts/cluster-administration/addons/
Deploying flannel manuallyを参考にインストールする。[root@k8sctrpln01 ~]# kubectl apply -f https://raw.githubusercontent.com/flannel-io/flannel/master/Documentation/kube-flannel.yml
Unable to connect to the server: dial tcp: lookup raw.githubusercontent.com on 172.16.0.2:53: server misbehaving
[root@k8sctrpln01 ~]# cat <<EOF > /etc/profile.d/k8s.sh
> export http_proxy=http://proxy01:3128
> export https_proxy=http://proxy01:3128
> EOF
[root@k8sctrpln01 ~]# source /etc/profile.d/k8s.sh
[root@k8sctrpln01 ~]# env | grep proxy
http_proxy=http://proxy01:3128
https_proxy=http://proxy01:3128
[root@k8sctrpln01 ~]# kubectl apply -f https://raw.githubusercontent.com/flannel-io/flannel/master/Documentation/kube-flannel.yml
Warning: policy/v1beta1 PodSecurityPolicy is deprecated in v1.21+, unavailable in v1.25+
podsecuritypolicy.policy/psp.flannel.unprivileged created
clusterrole.rbac.authorization.k8s.io/flannel created
clusterrolebinding.rbac.authorization.k8s.io/flannel created
serviceaccount/flannel created
configmap/kube-flannel-cfg created
daemonset.apps/kube-flannel-ds created
Init→Runningに遷移する。次いでcorednsの状態がContainerCreatingに遷移するのだが、Runningまで遷移しない。そしてkube-flannelはErrorになる始末。[root@k8sctrpln01 ~]# kubectl get pods --all-namespaces
NAMESPACE NAME READY STATUS RESTARTS AGE
kube-system coredns-6d4b75cb6d-66hl2 0/1 ContainerCreating 0 5m21s
kube-system coredns-6d4b75cb6d-vnw7j 0/1 ContainerCreating 0 5m21s
kube-system etcd-k8sctrpln01 1/1 Running 0 5m50s
kube-system kube-apiserver-k8sctrpln01 1/1 Running 0 5m36s
kube-system kube-controller-manager-k8sctrpln01 1/1 Running 0 5m51s
kube-system kube-flannel-ds-vdwnm 0/1 Error 1 (9s ago) 56s
kube-system kube-proxy-cktd6 1/1 Running 0 5m21s
kube-system kube-scheduler-k8sctrpln01 1/1 Running 0 5m50s
[root@k8sctrpln01 ~]# kubectl -n kube-system logs kube-flannel-ds-vdwnm
Defaulted container "kube-flannel" out of: kube-flannel, install-cni-plugin (init), install-cni (init)
I0528 22:14:46.576077       1 main.go:207] CLI flags config: {etcdEndpoints:http://127.0.0.1:4001,http://127.0.0.1:2379 etcdPrefix:/coreos.com/network etcdKeyfile: etcdCertfile: etcdCAFile: etcdUsername: etcdPassword: version:false kubeSubnetMgr:true kubeApiUrl: kubeAnnotationPrefix:flannel.alpha.coreos.com kubeConfigFile: iface:[] ifaceRegex:[] ipMasq:true ifaceCanReach: subnetFile:/run/flannel/subnet.env publicIP: publicIPv6: subnetLeaseRenewMargin:60 healthzIP:0.0.0.0 healthzPort:0 iptablesResyncSeconds:5 iptablesForwardRules:true netConfPath:/etc/kube-flannel/net-conf.json setNodeNetworkUnavailable:true}
W0528 22:14:46.576246       1 client_config.go:614] Neither --kubeconfig nor --master was specified.  Using the inClusterConfig.  This might not work.
I0528 22:14:46.773989       1 kube.go:121] Waiting 10m0s for node controller to sync
I0528 22:14:46.774494       1 kube.go:398] Starting kube subnet manager
I0528 22:14:47.774698       1 kube.go:128] Node controller sync successful
I0528 22:14:47.774727       1 main.go:227] Created subnet manager: Kubernetes Subnet Manager - k8sctrpln01
I0528 22:14:47.774733       1 main.go:230] Installing signal handlers
I0528 22:14:47.774886       1 main.go:463] Found network config - Backend type: vxlan
I0528 22:14:47.775008       1 match.go:195] Determining IP address of default interface
E0528 22:14:47.775135       1 main.go:270] Failed to find any valid interface to use: failed to get default interface: protocol not available
Failed to find any valid interface to use: failed to get default interface: protocol not availableで失敗しているのが直接原因の様子。色々と調べたり試したりしたが、解消できなかった。
※/run/flannel/subnet.envを手動作成してみたり、kubeadm resetしてみたり、kube-flannel.ymlを編集してインターフェースを指定してみたり。kube-flannel.ymlを使用したところ解消。とりあえずこれでいいや・・・
[root@k8sctrpln01 ~]# curl -s https://raw.githubusercontent.com/flannel-io/flannel/master/Documentation/kube-flannel.
yml | grep image | grep -v "#"
        image: rancher/mirrored-flannelcni-flannel-cni-plugin:v1.1.0
        image: rancher/mirrored-flannelcni-flannel:v0.18.0
        image: rancher/mirrored-flannelcni-flannel:v0.18.0
[root@k8sctrpln01 ~]# cat kube-flannel.yml | grep image | grep -v "#"
        image: rancher/mirrored-flannelcni-flannel-cni-plugin:v1.0.1
        image: rancher/mirrored-flannelcni-flannel:v0.16.3
        image: rancher/mirrored-flannelcni-flannel:v0.16.3
[root@k8sctrpln01 ~]# kubectl apply -f kube-flannel.yml
Warning: policy/v1beta1 PodSecurityPolicy is deprecated in v1.21+, unavailable in v1.25+
podsecuritypolicy.policy/psp.flannel.unprivileged configured
clusterrole.rbac.authorization.k8s.io/flannel unchanged
clusterrolebinding.rbac.authorization.k8s.io/flannel unchanged
serviceaccount/flannel unchanged
configmap/kube-flannel-cfg unchanged
daemonset.apps/kube-flannel-ds configured
[root@k8sctrpln01 ~]# kubectl get pods --all-namespaces
NAMESPACE     NAME                                  READY   STATUS    RESTARTS   AGE
kube-system   coredns-6d4b75cb6d-66hl2              1/1     Running   0          20m
kube-system   coredns-6d4b75cb6d-vnw7j              1/1     Running   0          20m
kube-system   etcd-k8sctrpln01                      1/1     Running   0          20m
kube-system   kube-apiserver-k8sctrpln01            1/1     Running   0          20m
kube-system   kube-controller-manager-k8sctrpln01   1/1     Running   0          20m
kube-system   kube-flannel-ds-vdzrd                 1/1     Running   0          68s
kube-system   kube-proxy-cktd6                      1/1     Running   0          20m
kube-system   kube-scheduler-k8sctrpln01            1/1     Running   0          20m
Readyになっている。[root@k8sctrpln01 ~]# kubectl get node
NAME STATUS ROLES AGE VERSION
k8sctrpln01 Ready control-plane 21m v1.24.1
コントロールプレーンノードの隔離
ノードの追加
ノードの複製、ホスト名やIPアドレスの変更が完了したところから記載する。[root@k8sworker01 ~]# yes | kubeadm reset
[reset] Reading configuration from the cluster...
[reset] FYI: You can look at this config file with 'kubectl -n kube-system get cm kubeadm-config -o yaml'
W0527 20:08:44.001097 2944 preflight.go:55] [reset] WARNING: Changes made to this host by 'kubeadm init' or 'kubeadm join' will be reverted.
[reset] Are you sure you want to proceed? [y/N]: [preflight] Running pre-flight checks
[reset] Stopping the kubelet service
[reset] Unmounting mounted directories in "/var/lib/kubelet"
W0527 20:09:23.058909 2944 cleanupnode.go:93] [reset] Failed to remove containers: [failed to remove running container 32ffc7801249a8077520b4876f5cd27f49929bb048ccb679d2387f012a9a2da8: output: E0527 20:08:53.857270 3260 remote_runtime.go:274] "RemovePodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = context deadline exceeded" podSandboxID="32ffc7801249a8077520b4876f5cd27f49929bb048ccb679d2387f012a9a2da8"
removing the pod sandbox "32ffc7801249a8077520b4876f5cd27f49929bb048ccb679d2387f012a9a2da8": rpc error: code = DeadlineExceeded desc = context deadline exceeded
, error: exit status 1, failed to remove running container f10a6ab2bba52dd9212ae35d13b4347a939d81df8d65a75b6e8509d3d7908784: output: E0527 20:08:57.084978 3347 remote_runtime.go:274] "RemovePodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = context deadline exceeded" podSandboxID="f10a6ab2bba52dd9212ae35d13b4347a939d81df8d65a75b6e8509d3d7908784"
removing the pod sandbox "f10a6ab2bba52dd9212ae35d13b4347a939d81df8d65a75b6e8509d3d7908784": rpc error: code = DeadlineExceeded desc = context deadline exceeded
, error: exit status 1, failed to stop running pod 208e167da6667e0dcf577d1cca0c57f44d8b698eaaaad96941d7bfdac26100f5: output: E0527 20:08:59.095956 3352 remote_runtime.go:248] "StopPodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = failed to stop container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\": an error occurs during waiting for container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\" to be killed: wait container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\": context deadline exceeded" podSandboxID="208e167da6667e0dcf577d1cca0c57f44d8b698eaaaad96941d7bfdac26100f5"
time="2022-05-27T20:08:59+09:00" level=fatal msg="stopping the pod sandbox \"208e167da6667e0dcf577d1cca0c57f44d8b698eaaaad96941d7bfdac26100f5\": rpc error: code = DeadlineExceeded desc = failed to stop container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\": an error occurs during waiting for container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\" to be killed: wait container \"0807cc39ba94fdbce032437b78e9ff4306bf3eed3b33b21292bedacacd1a5a86\": context deadline exceeded"
, error: exit status 1, failed to stop running pod 9d3c0e0634883d65e2dde44ecf40c2c7d31a2dc24a2063e48af923433840e2f8: output: E0527 20:09:01.107616 3388 remote_runtime.go:248] "StopPodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = context deadline exceeded" podSandboxID="9d3c0e0634883d65e2dde44ecf40c2c7d31a2dc24a2063e48af923433840e2f8"
time="2022-05-27T20:09:01+09:00" level=fatal msg="stopping the pod sandbox \"9d3c0e0634883d65e2dde44ecf40c2c7d31a2dc24a2063e48af923433840e2f8\": rpc error: code = DeadlineExceeded desc = context deadline exceeded"
, error: exit status 1, failed to remove running container 830472a335e3e7438337679bcfc7a16813f336eff1905e4f9111a56819ee5623: output: E0527 20:09:16.298865 3753 remote_runtime.go:274] "RemovePodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = context deadline exceeded" podSandboxID="830472a335e3e7438337679bcfc7a16813f336eff1905e4f9111a56819ee5623"
removing the pod sandbox "830472a335e3e7438337679bcfc7a16813f336eff1905e4f9111a56819ee5623": rpc error: code = DeadlineExceeded desc = context deadline exceeded
, error: exit status 1, failed to remove running container e0ce40c26ba17869724471443fcc7b0af25356e883fd1ab6753c2c2dcd0ecae4: output: E0527 20:09:23.058159 3807 remote_runtime.go:274] "RemovePodSandbox from runtime service failed" err="rpc error: code = DeadlineExceeded desc = context deadline exceeded" podSandboxID="e0ce40c26ba17869724471443fcc7b0af25356e883fd1ab6753c2c2dcd0ecae4"
removing the pod sandbox "e0ce40c26ba17869724471443fcc7b0af25356e883fd1ab6753c2c2dcd0ecae4": rpc error: code = DeadlineExceeded desc = context deadline exceeded
, error: exit status 1]
[reset] Deleting contents of directories: [/etc/kubernetes/manifests /etc/kubernetes/pki]
[reset] Deleting files: [/etc/kubernetes/admin.conf /etc/kubernetes/kubelet.conf /etc/kubernetes/bootstrap-kubelet.conf /etc/kubernetes/controller-manager.conf /etc/kubernetes/scheduler.conf]
[reset] Deleting contents of stateful directories: [/var/lib/etcd /var/lib/kubelet /var/lib/dockershim /var/run/kubernetes /var/lib/cni]
The reset process does not clean CNI configuration. To do so, you must remove /etc/cni/net.d
The reset process does not reset or clean up iptables rules or IPVS tables.
If you wish to reset iptables, you must do so manually by using the "iptables" command.
If your cluster was setup to utilize IPVS, run ipvsadm --clear (or similar)
to reset your system's IPVS tables.
The reset process does not clean your kubeconfig files and you must remove them manually.
Please, check the contents of the $HOME/.kube/config file.
[root@k8sworker01 ~]# ls -l $HOME/.kube/config
-rw-------. 1 root root 5635  5月 27 17:03 /root/.kube/config
[root@k8sworker01 ~]# rm -f $HOME/.kube/config
[root@k8sworker01 ~]# ip link
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN mode DEFAULT group default qlen 1000
    link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:17:78:f8 brd ff:ff:ff:ff:ff:ff
3: eth1: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:8d:4c:c5 brd ff:ff:ff:ff:ff:ff
4: eth2: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:07:f1:85 brd ff:ff:ff:ff:ff:ff
5: flannel.1: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1450 qdisc noqueue state UNKNOWN mode DEFAULT group default
    link/ether 12:d2:03:a5:d2:5a brd ff:ff:ff:ff:ff:ff
6: cni0: <NO-CARRIER,BROADCAST,MULTICAST,UP> mtu 1500 qdisc noqueue state DOWN mode DEFAULT group default qlen 1000
    link/ether 6a:55:d4:30:30:97 brd ff:ff:ff:ff:ff:ff
[root@k8sworker01 ~]# ip link delete cni0
[root@k8sworker01 ~]# ip link delete flannel.1
[root@k8sworker01 ~]# ip link
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN mode DEFAULT group default qlen 1000
    link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
2: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:17:78:f8 brd ff:ff:ff:ff:ff:ff
3: eth1: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:8d:4c:c5 brd ff:ff:ff:ff:ff:ff
4: eth2: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP mode DEFAULT group default qlen 1000
    link/ether 52:54:00:07:f1:85 brd ff:ff:ff:ff:ff:ff
[root@k8sworker01 ~]# firewall-cmd --list-services
dhcpv6-client etcd-client etcd-server snmp ssh
[root@k8sworker01 ~]# firewall-cmd --list-ports
6443/tcp 10250/tcp 10251/tcp 10252/tcp
[root@k8sworker01 ~]# firewall-cmd --add-port=30000-32767/tcp --permanent
success
[root@k8sworker01 ~]# firewall-cmd --remove-service={etcd-client,etcd-server} --permanent
success
[root@k8sworker01 ~]# firewall-cmd --remove-port={6443/tcp,10251/tcp,10252/tcp} --permanent
success
[root@k8sworker01 ~]# firewall-cmd --reload
success
[root@k8sworker01 ~]# firewall-cmd --list-services
dhcpv6-client snmp ssh
[root@k8sworker01 ~]# firewall-cmd --list-ports
10250/tcp 30000-32767/tcp
kubeadm initした際の標準出力に、ワーカノードをクラスタに参加させるkubeadm joinコマンドが表示されている。それを使っても構わないが、トークンの期限が24時間で更新が面倒なので、ここで無期限のトークンを作成してしまう。
zaki-hmkc.hatenablog.com[root@k8sctrpln01 ~]# kubeadm token list
TOKEN TTL EXPIRES USAGES DESCRIPTION EXTRA GROUPS
pbwo6h.lk8hjvpfuqroxf9u 20h 2022-05-28T08:27:45Z authentication,signing The default bootstrap token generated by 'kubeadm init'. system:bootstrappers:kubeadm:default-node-token
[root@k8sctrpln01 ~]# kubeadm token delete 1alk8n.8haf7p9cszxh2kw1
bootstrap token "1alk8n" deleted
[root@k8sctrpln01 ~]# kubeadm token create --ttl 0 --print-join-command
kubeadm join 172.16.0.11:6443 --token o133rw.oyma9inaboa1ra9w --discovery-token-ca-cert-hash sha256:fc839a2ff1689c9af8f302670a51c1c44e5a16b7d89304931b7cc9052a192caf
[root@k8sctrpln01 ~]# kubeadm token list
TOKEN                     TTL         EXPIRES   USAGES                   DESCRIPTION                                                EXTRA GROUPS
o133rw.oyma9inaboa1ra9w   <forever>   <never>   authentication,signing   <none>                                                     system:bootstrappers:kubeadm:default-node-token
[root@k8sworker01 ~]# kubeadm join 172.16.0.11:6443 --token o133rw.oyma9inaboa1ra9w --discovery-token-ca-cert-hash sha256:fc839a2ff1689c9af8f302670a51c1c44e5a16b7d89304931b7cc9052a192caf
[preflight] Running pre-flight checks
        [WARNING HTTPProxy]: Connection to "https://172.16.0.11" uses proxy "http://proxy01:3128". If that is not intended, adjust your proxy settings
[preflight] Reading configuration from the cluster...
[preflight] FYI: You can look at this config file with 'kubectl -n kube-system get cm kubeadm-config -o yaml'
[kubelet-start] Writing kubelet configuration to file "/var/lib/kubelet/config.yaml"
[kubelet-start] Writing kubelet environment file with flags to file "/var/lib/kubelet/kubeadm-flags.env"
[kubelet-start] Starting the kubelet
[kubelet-start] Waiting for the kubelet to perform the TLS Bootstrap...

This node has joined the cluster:
* Certificate signing request was sent to apiserver and a response was received.
* The Kubelet was informed of the new secure connection details.

Run 'kubectl get nodes' on the control-plane to see this node join the cluster.
[root@k8sctrpln01 ~]# kubectl get node
NAME          STATUS   ROLES           AGE     VERSION
k8sctrpln01   Ready    control-plane   65m     v1.24.1
k8sworker01   Ready    <none>          3m23s   v1.24.1
[root@k8sctrpln01 ~]# kubectl get node
NAME          STATUS   ROLES           AGE     VERSION
k8sctrpln01   Ready    control-plane   69m     v1.24.1
k8sworker01   Ready    <none>          6m42s   v1.24.1
k8sworker02   Ready    <none>          55s     v1.24.1
-o wideオプションが何かと便利。[root@k8sctrpln01 ~]# kubectl get node -o wide
NAME STATUS ROLES AGE VERSION INTERNAL-IP EXTERNAL-IP OS-IMAGE KERNEL-VERSION CONTAINER-RUNTIME
k8sctrpln01 Ready control-plane 69m v1.24.1 172.16.0.11 <none> CentOS Linux 7 (Core) 3.10.0-1160.66.1.el7.x86_64 containerd://1.6.4
k8sworker01 Ready <none> 6m53s v1.24.1 172.16.0.12 <none> CentOS Linux 7 (Core) 3.10.0-1160.66.1.el7.x86_64 containerd://1.6.4
k8sworker02 Ready <none> 66s v1.24.1 172.16.0.13 <none> CentOS Linux 7 (Core) 3.10.0-1160.66.1.el7.x86_64 containerd://1.6.4
(オプション)コントロールプレーンノード以外のマシンからのクラスター操作
(オプション)APIサーバーをlocalhostへプロキシする
クリーンアップ
次の手順
あとがき
トラブルの要因はいずれもパッケージのバージョンに起因するものだった。バージョンアップを躊躇させてくるね・・・参考記事
Kubernetes記事まとめ
概要
- Kubernetes記事の目次ページ。
目次
- Kubernetes環境を構築してみた
- Kubernetes環境でアプリケーションの外部公開をしてみた
- Kubernetes環境でDNSサービスを構築してみた
- Kubernetes環境でVPNサーバサービスを構築してみた
- Kubernetes環境でForward Proxyサービスを構築してみた
- Kubernetes環境でReverse Proxyサービスを構築してみた
- Kubernetes環境でSyslog監視サービスを構築してみた
- Kubernetes環境でSNMP trap監視サービスを構築してみた
- Kubernetes環境にDashboardでアクセスしてみた
参考記事
TIPS: はんだ付けのために揃えた工具一式
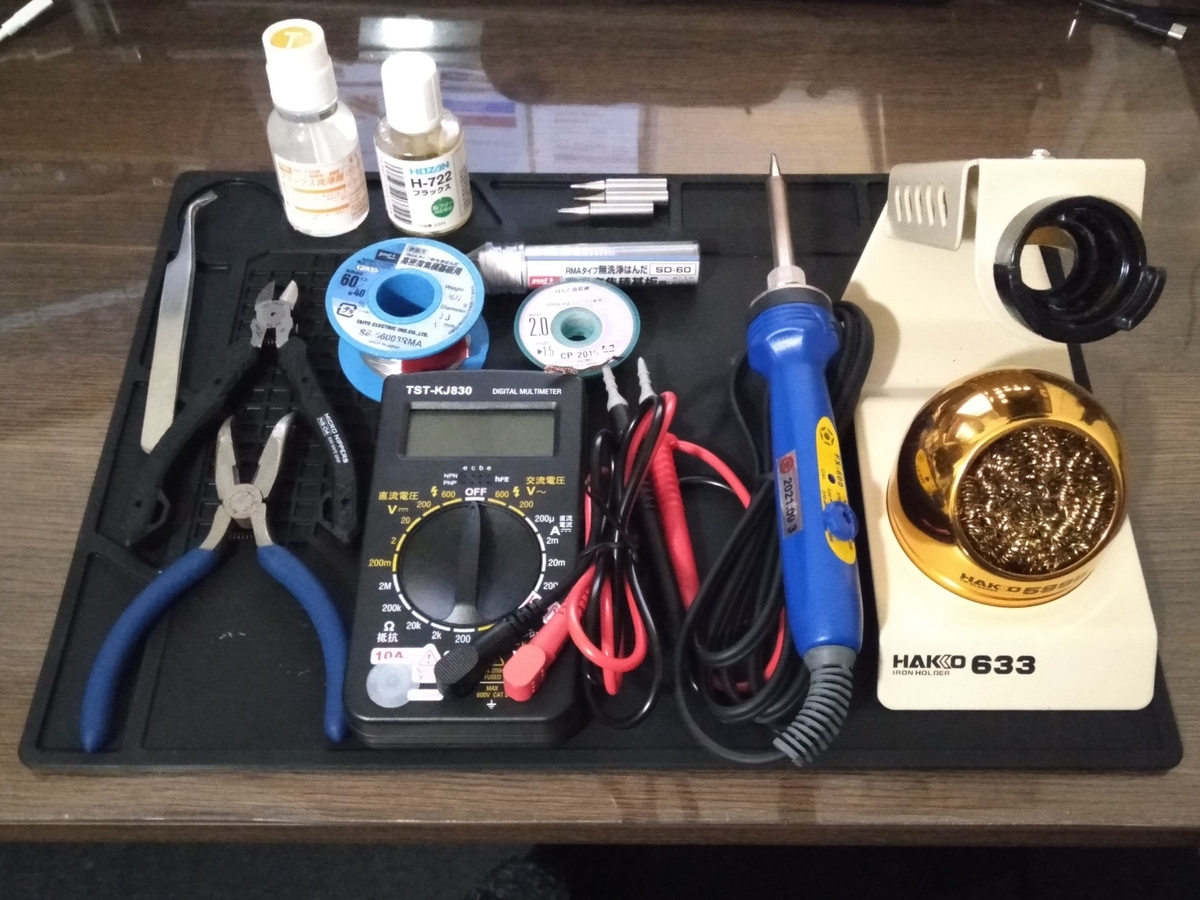
目次
概要
はんだ付けを始めるにあたり揃えたツールの記録。
はんだごて
- FX600-02
温度調節機能はマスト。
リンク
こて先
- T18-D16
汎用性が高く、ほとんどの素子に対応した。
リンク
- T18-CF1
切断面にしかはんだが付かないので引きはんだがやりやすいと思い購入。しかし使いこなせず。先端が丸くないので狭い場所に有利。
リンク
- T18-CF2
T18-CF2の少し太いバージョン。
リンク
こて台
- 633-01
金属のクリーナーなのでこて先の温度を下げにくい。
リンク
はんだ(φ0.3mm)
- SE-06003RMA
かなり細い。
リンク
はんだ(φ0.6mm)
- SD-60
やや細い。
リンク
はんだ吸い取り線
- CP-2015
使いやすい太さのものを選定。
リンク
フラックス
- H-722
ピッチが狭い場所に極めて有効。熱しすぎてフラックスが蒸発したはんだの復活にも使える。
リンク
フラックスクリーナー
- BS-T20B
フラックスの掃除に必要。
リンク
ピンセット
- PT-06
真っ直ぐのものや、逆作用ピンセットとも迷った。
リンク
ニッパー
- NS-04
まだ出番はないが、スルーホール実装で素子の足を切るシーンで使う予定。
リンク
ペンチ
手持ちの適当なもの。
ドライバー
手持ちの適当なもの。
テスター
- TST-KJ830
導通チェックができてコンパクトなものを選択。
リンク
作業マット
- KaiYi
青い製品が多かったので黒い製品にしてみた。
リンク
